# Introduction

Explore SRE.ai’s technical documentation

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FbahzPBrV2PfxDtfbU7pL%2FBlue%20Hue.png?alt=media&amp;token=c38aaedc-a7e0-4ebd-bf9a-3283a9db1a7f" alt="" width="563"><figcaption></figcaption></figure>

## Overview

SRE.ai is a cross-platform application that **revamps DevOps with AI-driven assistance, streamlining workflows, saving time,** and **boosting productivity**.

SRE.ai utilizes **integrations, customizable automations, and chat** to streamline:

* Committing
* Merging
* Building
* Releasing&#x20;
* Maintenance

{% hint style="success" %}
SRE.ai offers flexibility by allowing teams to choose the tools, processes, and strategies that work best for them.
{% endhint %}

<table data-view="cards"><thead><tr><th></th><th></th><th data-hidden data-card-cover data-type="files"></th><th data-hidden></th><th data-hidden data-card-target data-type="content-ref"></th></tr></thead><tbody><tr><td><strong>Quickstart guide</strong></td><td>Get started with setting up SRE.ai</td><td></td><td></td><td><a href="/setting-up-sre.ai/quickstart">Quickstart guide</a></td></tr><tr><td><strong>Integrations</strong></td><td>Learn how to integrate other applications with SRE.ai</td><td></td><td></td><td><a href="/setting-up-sre.ai/integrations">Integrations</a></td></tr><tr><td><strong>Agents</strong></td><td>Learn about SRE.ai's agentic capabilities.</td><td></td><td></td><td><a href="/using-sre.ai/agents">Agents</a></td></tr><tr><td><strong>Automations</strong></td><td>Learn about SRE.ai's customizable automations</td><td></td><td></td><td><a href="/using-sre.ai/automations">Automations</a></td></tr><tr><td><strong>Changes</strong></td><td>Learn how SRE.ai tracks changes</td><td></td><td></td><td><a href="/using-sre.ai/changes">Changes</a></td></tr><tr><td><strong>Use cases</strong></td><td>Learn where and how SRE.ai can fit into your day.</td><td></td><td></td><td><a href="/use-cases/pipeline-automation">Use Cases</a></td></tr></tbody></table>

<table data-card-size="large" data-view="cards"><thead><tr><th></th><th></th><th data-hidden data-type="image">Cover image (dark)</th><th data-hidden data-card-cover data-type="image">Cover image</th><th data-hidden data-type="image">Cover image (dark)</th><th data-hidden data-type="image">Cover image (dark)</th><th data-hidden data-type="image">Cover image (dark)</th><th data-hidden data-card-cover-dark data-type="image">Cover image (dark)</th></tr></thead><tbody><tr><td><strong>Proactive system intelligence</strong></td><td><p>Transform reactive monitoring into predictive insights by correlating performance data across systems. </p><p></p><p>Identify potential issues before they impact users and automatically surface root cause analysis.</p></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2Ftja7KLqCv8CPcAmSji7Z%2FMonitorLight.png?alt=media&amp;token=19d9676d-3348-4221-8708-f6ae679e2d23">MonitorLight.png</a></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FDf1FE9kpg6kIkerUNnKD%2FMonitorM.png?alt=media&amp;token=bfd54d14-533d-48e5-8797-19fec9888b27">MonitorM.png</a></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FDf1FE9kpg6kIkerUNnKD%2FMonitorM.png?alt=media&amp;token=bfd54d14-533d-48e5-8797-19fec9888b27">MonitorM.png</a></td></tr><tr><td><strong>Intelligent CI/CD orchestration</strong></td><td><p>Optimize build pipelines with intelligent test selection, parallel execution strategies, and dependency-aware scheduling. </p><p></p><p>Reduce build times while maintaining code quality and deployment reliability.</p></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FuGZ8NvuR0Cu8mQQSjOVY%2FBuildDark.png?alt=media&amp;token=de95cec1-8f3d-4e68-85a5-512a4a1e1faf">BuildDark.png</a></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FzRFdHAJqCraa2EO8Uu3F%2FBuild%20Light.png?alt=media&amp;token=64329cb7-71a8-4965-9020-97b2e4d48096">Build Light.png</a></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FUmYzDnKo0JhAG6YDwAxn%2FBuildM.png?alt=media&amp;token=3b45ec9d-8519-4a1d-b550-ef80bd5c4544">BuildM.png</a></td><td></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FUmYzDnKo0JhAG6YDwAxn%2FBuildM.png?alt=media&amp;token=3b45ec9d-8519-4a1d-b550-ef80bd5c4544">BuildM.png</a></td></tr><tr><td><strong>Adaptive testing strategy</strong></td><td><p>Intelligently prioritize and execute tests based on code changes, risk assessment, and historical failure patterns. </p><p></p><p>Maintain comprehensive coverage while optimizing testing efficiency and feedback cycles.</p></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FStwGrk1WuEaLyTxBH1np%2FTestLight.png?alt=media&amp;token=0b1df835-d3d1-4d43-b93c-7b97afbb7ea3">TestLight.png</a></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FQussol1AnoiiRNxEmns2%2FTestM.png?alt=media&amp;token=b08f47ad-d738-41db-830b-6080da2357cd">TestM.png</a></td><td></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FQussol1AnoiiRNxEmns2%2FTestM.png?alt=media&amp;token=b08f47ad-d738-41db-830b-6080da2357cd">TestM.png</a></td></tr><tr><td><strong>Security automation</strong></td><td>Establish automated security scanning in development workflows and sync role-based permissions across platforms.</td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FwNp6yDVUrZQ4N1DcbiT5%2FProtectLight.png?alt=media&amp;token=0b47230f-c35e-495f-a434-288eef1a0521">ProtectLight.png</a></td><td></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2Ff6DocjfeyokHoBrPbotu%2FProtectM.png?alt=media&amp;token=8c28e4a2-b3ed-459f-8069-14c61acc89c8">ProtectM.png</a></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2Ff6DocjfeyokHoBrPbotu%2FProtectM.png?alt=media&amp;token=8c28e4a2-b3ed-459f-8069-14c61acc89c8">ProtectM.png</a></td></tr><tr><td><strong>Knowledge management automation</strong></td><td><p>Auto-document code changes, deployment activities, and incident resolutions. </p><p></p><p>Eliminate outdated runbooks and ensure tribal knowledge is captured and searchable.</p></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FnVtPW34xzBUXwon78QXA%2FDocument%20Light.png?alt=media&amp;token=6ef11e07-c284-4b9e-9ac6-b0676b954ae5">Document Light.png</a></td><td></td><td></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FXxrmx9pRFLxP5dFqZi3x%2FDocumentM.png?alt=media&amp;token=2a61bd08-91c5-4165-81d2-5a26ba1d482d">DocumentM.png</a></td></tr><tr><td><strong>Safe deployment automation</strong></td><td><p>Orchestrate complex multi-environment releases with automated rollback protection, progressive deployment strategies, and real-time validation. </p><p></p><p>Ensure consistent deployments across development, staging, and production.</p></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2F8Z15WM6l0UJcib4yz3Yn%2FReleaseLight.png?alt=media&amp;token=b49c26ac-4eab-4c20-88ea-21f6ff8982a9">ReleaseLight.png</a></td><td></td><td></td><td></td><td><a href="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2Fg2qLYjPcMuwJR2LQhifY%2FReleaseM.png?alt=media&amp;token=016f6ab5-0a62-43d6-9fe6-3b58f9fb49da">ReleaseM.png</a></td></tr></tbody></table>


# SRE.ai TDX Demo

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2Fy0w8rqtFS6pSSOfL4pBb%2Funknown.png?alt=media&amp;token=1b146c20-93aa-43cd-9a20-38a51fd82ac6" alt=""><figcaption></figcaption></figure>

1. Open up a tab in chrome with <https://app.dev.sre.ai/>, [Jira](https://sre.atlassian.net/jira/software/projects/KAN/boards/1), and our [demo salesforce org](https://sre-ai--demo1.sandbox.my.salesforce.com/). They are all bookmarked. Login info is below.
   1. <https://app.dev.sre.ai/>

      Sign in using the "Continue with email" option.

      Username: <demo1user@sre.ai>

      Password: StandardCap26<br>

      <figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FrJtXkh96NJOagTvMQzF4%2FScreenshot%202026-04-23%20at%208.08.28%E2%80%AFPM.png?alt=media&amp;token=319a0047-4041-4ba9-a473-3a13903e4cc5" alt=""><figcaption></figcaption></figure>
   2. [Jira](https://sre.atlassian.net/jira/software/projects/KAN/boards/1)\
      Username: <demo1user@sre.ai>\
      Password: sre\_demo\_450
   3. [Demo salesforce org](https://sre-ai--demo1.sandbox.my.salesforce.com/)\
      Username: demo1user\@sre.ai.demo1\
      Password: sre\_demo\_450<br>
2. In Jira, assign yourself a welcome banner component ticket, an automated approval process ticket, and an auto-create onboarding tasks ticket. These represent real changes that will be made to our org.

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FoA0VkZ8KCdtkaH6FuGRa%2Funknown.png?alt=media&amp;token=089942ff-2fe4-4bd0-a06f-4a8669596947" alt="" width="316"><figcaption></figcaption></figure>

3. Switch over to SRE and expand “Recent Chats.” You’ll see that three workflows have been started on your behalf.

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FTDWJNOgHhBlcSutkq8Bw%2Funknown.png?alt=media&amp;token=5b676927-f373-4ee1-b928-34a688c5a0ee" alt=""><figcaption></figcaption></figure>

4. When you see the design task has been completed, review the generated document, then click “Implement the solution”. Select the “demo” salesforce org when prompted.

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FYX4QRvtOxqLyDk83rvLP%2Funknown.png?alt=media&amp;token=0b6e05a7-5f0e-4829-be06-587616f5f0bf" alt="" width="375"><figcaption></figcaption></figure>

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FTWMEC8dk1z9vNz243g2e%2Funknown.png?alt=media&amp;token=4d9ddca0-24d2-4419-b6d0-1d393159be45" alt=""><figcaption></figcaption></figure>

5. You’ll see the task get completed step by step. Feel free to do multiple workflows at a time.&#x20;

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FUFaPb6LICB3poGpph3kV%2Funknown.png?alt=media&amp;token=ee9cca6a-b670-4e3b-822d-2471154374a3" alt="" width="375"><figcaption></figcaption></figure>

{% hint style="warning" %}
This step can take a while, since SRE.ai is generating all the code for your change, and validating it in the target org.&#x20;

While that’s happening, check out the pipeline tab and view our quality gates, or ask us about automations!
{% endhint %}

<br>

6. When an implementation is finished, you’ll be notified, and will be able to view the change in your salesforce org!

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FtsbJHaCW9ET2elJqSsI8%2Funknown.png?alt=media&amp;token=b547fe9f-a925-4f71-b4be-3823cfa7d93a" alt="" width="375"><figcaption></figcaption></figure>

7. &#x20;Refresh your Org to see the new “Seller Home” tab!

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FLDbI6Nd7MvQ7SF6h6qHw%2Funknown.png?alt=media&amp;token=1552c835-7a57-4268-a110-0535a2b29149" alt=""><figcaption></figcaption></figure>

{% hint style="info" %}
**Bonus:**

Create your own ticket for yourself!&#x20;

See if you can go through the whole flow and view your change.
{% endhint %}

<br>


# Quickstart guide

Learn how to set up SRE.ai

## Overview

SRE.ai works by connecting your **Salesforce environments** and your **GitHub repositories**, then orchestrating how changes move between them.

The three steps below establish that foundation.

**Adding your Salesforce orgs** gives SRE.ai access to the environments it will deploy to and monitor. Without them, there's nothing to release to.

**Connecting GitHub** gives SRE.ai visibility into your code, **branches**, **commits**, and **pull requests**. This is what SRE.ai watches to detect changes and trigger **automations**.

**Configuring your pipeline** ties the two together. It maps your GitHub **branches** to your Salesforce **environments** and defines the **stages** a change must pass through before reaching production.

Once all three are in place, SRE.ai has everything it needs to orchestrate your **deployments**, run **automations**, and provide **AI assistance** across your workflow.

### Step 1: Add Salesforce Orgs

Connect your Salesforce organizations to SRE.ai.

{% hint style="success" %}
You can connect both production orgs and sandboxes.
{% endhint %}

#### Prerequisites

* Salesforce credentials with one of these permissions:
  * Modify All Data
  * Modify Metadata Through Metadata API Functions
* Access to a developer account for sandboxes

{% columns %}
{% column %}
**Connect a Production Org**

1. In the Salesforce Orgs page, **click Connect Salesforce Org**
2. Select **Production** from the dropdown menu
3. You'll be redirected to the Salesforce login page
4. Enter your Salesforce credentials and click **Log In**
5. Authorize SRE.ai to access your org
6. Once complete, you'll be returned to SRE.ai with your production org connected
   {% endcolumn %}

{% column %}
**Connect a Sandbox**

1. In the Salesforce Orgs page, **click Connect Salesforce Org**
2. Select **Sandbox** from the dropdown menu
3. You'll be redirected to the Salesforce sandbox login page (note: the URL will show `test.salesforce.com`)
4. Enter your sandbox credentials and click **Log In to Sandbox**
5. Authorize SRE.ai to access your sandbox
6. Once complete, you'll be returned to SRE.ai with your sandbox connected
   {% endcolumn %}
   {% endcolumns %}

#### Notes

* You can connect multiple production orgs and sandboxes
* SRE.ai uses SSO for Salesforce connections, no tokens or keys required
* Connected Salesforce orgs will appear in your Salesforce Orgs list and be available for deployments and automations
* If an org's session expires, SRE.ai will prompt you to reauthenticate using the same SSO flow
* [Read SRE.ai's Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs) to learn more

### Step 2: Connect GitHub account

Link your GitHub account to enable SRE.ai to manage repositories, track branches, create pull requests, and trigger automations based on Git events.

{% hint style="danger" %}
**Connecting to GitHub requires admin approval in your GitHub org.**\
If you are not a GitHub admin, adding the integration will create a request that your org admin can approve.\
\
Read [GitHub's documentation on installing apps](https://docs.github.com/en/apps/using-github-apps/installing-a-github-app-from-a-third-party) to learn more about approvals.\
\
**Select your organization, not your personal account.**\
Clicking your personal account instead of your organization will connect to the wrong context.
{% endhint %}

**Prerequisites**

* A GitHub account with access to the repositories you want to connect
* Permission to install GitHub Apps on your organization (if connecting an organization's repositories)

**Connect GitHub**

1. In the Integrations page, click **+ Add Integration** in the top right of the screen and select **GitHub**
2. You'll be redirected to GitHub to install the SRE.ai GitHub App
3. GitHub will ask: "Where do you want to install the SRE.ai GitHub App?"
4. Select your organization (not your personal account)
5. On the repository access screen, choose your access scope:
   * **Only select repositories:** Choose specific repositories to connect (recommended)
   * Select at least one repository from the dropdown
6. Review the permissions SRE.ai is requesting:
   * Read access to metadata
   * Read and write access to code, pull requests, and repository hooks
7. Click **Install** (or **Update access** if modifying an existing installation)
8. You'll be returned to SRE.ai with your GitHub account connected

#### Notes

* You can modify repository access later through GitHub's application settings
* SRE.ai only requests the permissions necessary to manage code, PRs, and hooks. No organization administration permissions are required
* Read [SRE.ai's Integrations documentation](/setting-up-sre.ai/integrations#sso) to learn more

### Step 3: Configure pipeline

Set up your CI/CD pipeline to define how changes flow from development through production.

#### Prerequisites

* At least one Salesforce instance connected (Step 1)
* GitHub account connected (Step 2)

#### Configure your pipeline

1. From the Command Center welcome screen, click **Configure Pipeline**
2. SRE.ai will present preset pipeline templates
3. Select a template that matches your workflow, or start with a default and customize

{% hint style="info" %}
The standard pipeline progression flows left to right:

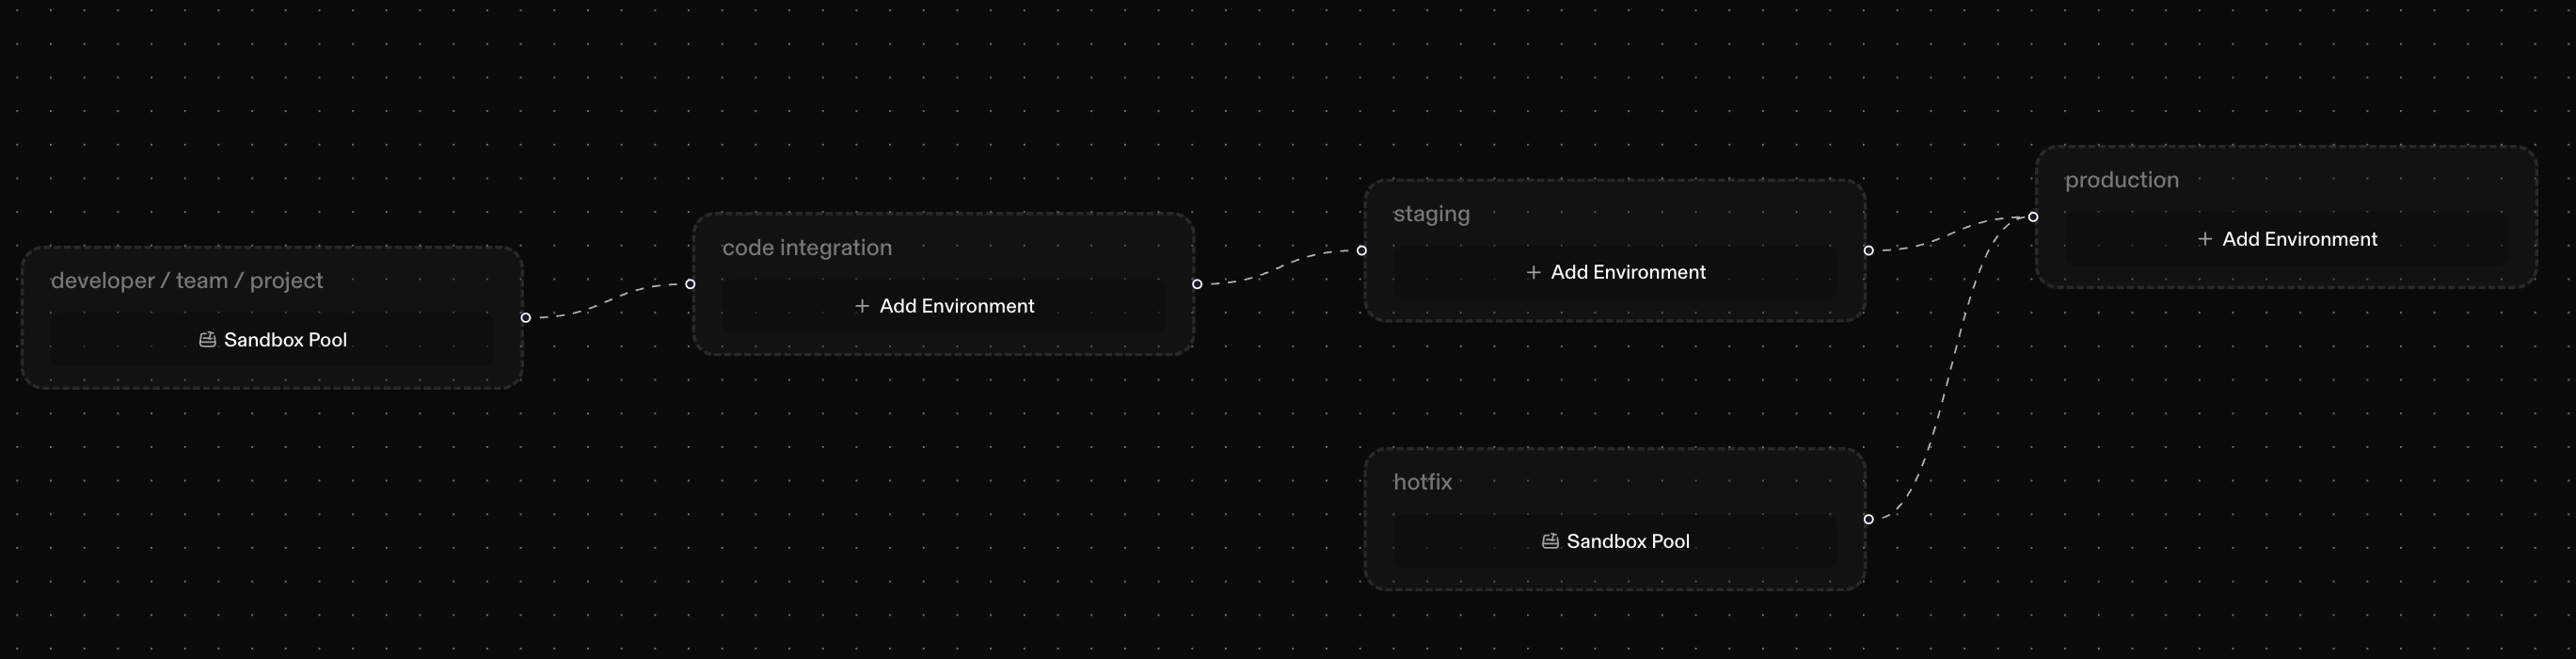
**Developer/Team** → **Integration** → **Staging** → **Production**

A hotfix stage can branch off from staging and connect directly to production for emergency fixes.

Read [SRE.ai's Pipeline documentation](/setting-up-sre.ai/pipelines) to learn more.
{% endhint %}

#### Map stages to branches and environments

Your pipeline consists of stages that represent phases in your deployment lifecycle. Each stage must be mapped to a branch and to one or more Salesforce environments.

1. Click on a stage to open the Stage Details panel
2. Configure the branch that this stage tracks
3. Click **Add Environment** to map the stage to a Salesforce org
4. Select from your connected Salesforce Orgs
5. A green checkmark indicates a validated connection
6. Repeat for each stage in your pipeline

{% hint style="warning" %}
Salesforce orgs mapped to active pipeline stages cannot be set to Inactive.<br>

To deactivate an org, remove it from all active pipeline stages first.
{% endhint %}

#### Configure quality gates

Quality gates define the criteria that must be met before changes can advance to the next stage.

1. Within the Stage Details panel, locate the Quality Gates section
2. Configure the gates for this stage:
   * **Code review:** enable and set the severity level that blocks promotion (Critical, High, or Medium)
   * **Code coverage:** require a minimum percentage (75%, 80%, 85%, or 90%)
   * **Test level:** set which tests run during deployment (unspecified, none, specified, local, or all org tests)
   * **Pull requests:** require a pull request before changes advance to the next stage

{% hint style="danger" %}
To complete pipeline setup, you need:

* At least two stages (e.g., Development → Production)
* At least one environment mapped to a stage
  {% endhint %}

### Next steps

Once you've completed these three steps, your SRE.ai environment is ready to use. You can now:

* **Use the Command Center chat** to interact with your environments and get AI assistance
* **Create Automations** to orchestrate workflows based on triggers
* **Track Changes** as you develop and deploy features
* **Use Agents** to design, build, and deploy with AI assistance

For more detailed information on each feature, see the relevant documentation sections.


# Salesforce Orgs

Learn how to manage your Salesforce Orgs in SRE.ai

## Overview

SRE.ai is built to manage and automate **Salesforce deployments**. **Salesforce Orgs** is where you establish that foundation.

Without connected orgs, SRE.ai has no environments to deploy to, monitor, or manage.

Everything from **pipeline stages** to **chat-driven deployments** depends on at least one connected org.

**Salesforce Orgs** lets you connect the Salesforce organizations SRE.ai will work with.

**SSO** is required when connecting for the first time, whether to a **Production Org** or a **Sandbox**.

{% hint style="success" %}
With SSO through Salesforce Orgs, SRE.ai does not require keys or tokens to connect to Salesforce.
{% endhint %}

## Core capabilities

Once connected, SRE.ai can:

* Automate deployments
* Automate sandbox testing
* Manage Salesforce organizations through a chat interface

## How it works

The Salesforce Orgs page lists your connected Salesforce orgs.

Each org displays a **type indicator** showing what kind of org it is:

* **Production:** a production org (`login.salesforce.com`)
* **Sandbox:** a sandbox org (`test.salesforce.com`)
* **Developer Edition:** a developer edition org

{% hint style="danger" %}
**Inactive connections are hidden in Chat.**

When a Salesforce connection is marked as Inactive, it will not appear as an option in any Chat entry point, including commit, deploy, design, and build workflows.

Set a connection back to Active to make it available again.

**An org cannot be set to Inactive while it is mapped to active pipeline environments.**

Remove it from all active pipeline stages first, then deactivate it.
{% endhint %}

The following table elements can be customized:

* Status
  * Active
  * Inactive
* Filter by creator
  * Filter the list to show only orgs created by a specific team member
* Visible columns
  * Status
  * Created By
  * Last Updated
* Number of rows per page
  * 10
  * 20
  * 30
  * 50
  * 100

### Connection health

Each connected org displays a health status that reflects whether SRE.ai can currently authenticate with it:

* **Connected:** the session is valid, and the org is reachable
* **Disconnected:** the session has expired or been revoked. This status is displayed as a red severity badge to signal that the org requires attention

The connection status is shown as an icon in the **Connection** column of the Salesforce Orgs table.

When an org is shown as Disconnected, a **Reconnect** button appears inline in that org's row. Click the reconnect button to re-authenticate using the same SSO flow used when you first connected the org.

{% hint style="info" %}
Reauthenticating through the Reconnect button follows the same SSO flow used when you first connected the org. No new credentials or tokens are required.
{% endhint %}

## **Setup**

#### Prerequisites

* Salesforce credentials with one of these permissions:
  * Modify All Data
  * Modify Metadata Through Metadata API Functions
* Access to a developer account for sandboxes

{% columns %}
{% column %}
**Connect a Production Org**

1. In the Salesforce Orgs page, **click Connect Salesforce Org**
2. Select **Production** from the dropdown menu
3. You'll be redirected to the Salesforce login page (note: the URL will show `login.salesforce.com`)
4. Enter your Salesforce credentials and click **Log In**
5. Authorize SRE.ai to access your org
6. Once complete, you'll be returned to SRE.ai with your production org connected
   {% endcolumn %}

{% column %}
**Connect a Sandbox**

1. In the Salesforce Orgs page, **click Connect Salesforce Org**
2. Select **Sandbox** from the dropdown menu
3. You'll be redirected to the Salesforce sandbox login page (note: the URL will show `test.salesforce.com`)
4. Enter your sandbox credentials and click **Log In to Sandbox**
5. Authorize SRE.ai to access your sandbox
6. Once complete, you'll be returned to SRE.ai with your sandbox connected
   {% endcolumn %}
   {% endcolumns %}


# Integrations

Learn how to manage integrations with various third-party applications

## Overview

Integrations are how SRE.ai connects to the tools beyond Salesforce:

**GitHub is the core integration,** without it, SRE.ai cannot track **branches**, trigger **automations**, or manage **pull requests**.

The remaining integrations further extend SRE.ai's reach, enabling it to serve as a truly cross-platform **DevOps assistant**.

{% hint style="info" %}
Integrations rely on various connection methods such as **SSO**, **OAuth**, and **API keys**.
{% endhint %}

## Core capabilities

SRE.ai's Integrations feature supports five applications:

* GitHub
* GitLab
* Jira
* Microsoft Teams
* Supabase

### Integrations page

If no integrations have been configured yet, the Integrations page displays an empty state with a **Connect an integration** button. Click it to begin adding your first integration.

{% hint style="info" %}
**Salesforce is not managed here.**

To connect a Salesforce org, navigate to **Salesforce Orgs** instead.

The Integrations page covers third-party tools: GitHub, GitLab, Jira, Microsoft Teams, and Supabase.
{% endhint %}

Once at least one integration is configured, the page displays a table of your connected integrations.

## Setup

### SSO

GitHub uses SSO, redirecting the user to the relevant sign-in page when connecting for the first time:

#### GitHub

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn about connecting GitHub to SRE.ai</strong></mark></summary>

1. In the Integrations page, click **+ Add Integration** in the top right of the screen and select **GitHub**
2. You'll be redirected to GitHub to install the SRE.ai GitHub App
3. GitHub will ask: "Where do you want to install the SRE.ai GitHub App?"
4. Select your organization (not your personal account)
5. On the repository access screen, choose your access scope:
   * **Only select repositories:** Choose specific repositories to connect (recommended)
   * Select at least one repository from the dropdown
6. Review the permissions SRE.ai is requesting:
   * Read access to metadata
   * Read and write access to code, pull requests, and repository hooks
7. Click **Install** (or **Update access** if modifying an existing installation)
8. You'll be returned to SRE.ai with your GitHub account connected

{% hint style="warning" %}
**Webhook signature verification is enforced.**

SRE.ai verifies the signature of every incoming webhook from GitHub using the secret configured for your integration.\
\
Webhook requests with a missing or invalid signature are rejected with a `401 Unauthorized` response and will not trigger any pipeline actions.

Ensure the webhook secret in your GitHub repository settings matches the one stored in SRE.ai. A mismatch will cause all webhook events to be rejected.
{% endhint %}

**Viewing enabled repositories:**

After connecting, the Integrations table shows your GitHub integration along with the repositories currently enabled for SRE.ai.

You can see at a glance which repos are accessible without leaving the page.

**Managing repository access:**

To add or remove repositories after the initial setup, use the repository management button in the GitHub row of the Integrations table. This takes you directly to GitHub's repository selection UI.

There's no need to reinstall or fully re-integrate the GitHub App.

</details>

### OAuth

The following Integrations require OAuth client IDs and OAuth client secrets to connect to SRE.ai:

* GitLab
* Jira

#### GitLab

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn about connecting GitLab to SRE.ai</strong></mark></summary>

Connecting to GitLab requires three items:

* GitLab URL
  * Use <https://gitlab.com> for GitLab.com or your self-hosted URL
* OAuth Client ID
  * [Read GitLab's documentation](https://docs.gitlab.com/integration/oauth_provider/) to learn about the OAuth Client ID
* OAuth Client Secret
  * [Read GitLab's documentation](https://docs.gitlab.com/integration/oauth_provider/) to learn about the OAuth Client Secret

Users who don't yet have OAuth credentials can create the credentials in [GitLab's settings](https://gitlab.com/-/user_settings/applications).

{% hint style="warning" %}
**Webhook signature verification is enforced.**

SRE.ai verifies the signature of every incoming webhook from GitLab using the secret token configured for your integration.\
\
Webhook requests with a missing or invalid `X-Gitlab-Token` payload are rejected with a `401 Unauthorized` response and will not trigger any pipeline actions.

Ensure the secret token in your GitLab webhook settings matches the one stored in SRE.ai. A mismatch will cause all webhook events to be rejected.
{% endhint %}

</details>

#### Jira

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn about connecting Jira to SRE.ai</strong></mark></summary>

If your team uses Jira for issue tracking, you can connect it to SRE.ai to link deployments with tickets and automate status updates.

**Prerequisites**

* Access to the [Atlassian Developer Console](https://developer.atlassian.com/console/myapps/)
* Permission to create OAuth apps in your Atlassian workspace (admin rights may be required)

**Step 1: Create an OAuth App in Atlassian**

1. Go to the [Atlassian Developer Console](https://developer.atlassian.com/console/myapps/)
2. Log in with your Atlassian account
3. Click **Create** → **OAuth 2.0 integration**
4. Enter a name for the app (e.g., "SRE-ai")
5. Agree to the developer terms and click **Create**

**Step 2: Configure Permissions**

1. In your new app, go to **Permissions** in the left sidebar
2. Find the **Jira API** and click **Add**
3. Configure the following scopes:
   * `read:jira-work` — Allows SRE.ai to view issues and projects
   * `write:jira-work` — Allows SRE.ai to create and update issues
   * `read:jira-user` — Allows SRE.ai to read user information
   * `offline_access` — Allows SRE.ai to maintain access via refresh tokens
4. Click **Save**

**Step 3: Configure Authorization**

1. Go to **Authorization** in the left sidebar
2. Next to "OAuth 2.0 (3LO)", click **Add**
3. You'll need to enter a callback URL—get this from SRE.ai:
   * In SRE.ai, go to **Integrations**
   * Click **Add Integration** → **Jira**
   * Copy the callback URL shown in the connection dialog
4. Paste the callback URL into Atlassian and save

**Step 4: Get Your OAuth Credentials**

1. In the Atlassian Developer Console, go to **Settings** in the left sidebar
2. Copy your **Client ID**
3. Create a new **Client Secret** and copy it

**Step 5: Connect in SRE.ai**

1. In SRE.ai, go to **Integrations**
2. Click **Add Integration** → **Jira**
3. Enter your OAuth Client ID and OAuth Client Secret
4. Click **Connect Jira**
5. You'll be redirected to Atlassian to authorize the connection
6. Select the Atlassian site you want to connect to and click **Accept**
7. You'll be returned to SRE.ai with Jira connected

</details>

### Webhook URL

SRE.ai uses a Webhook URL to configure its Microsoft Teams integration.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn about connecting Microsoft Teams to SRE.ai</strong></mark></summary>

Connecting to Microsoft Teams requires two items:

* Channel Name
* Webhook URL
  * Found in Teams channel → More options (⋯) → Connectors → Incoming Webhook

</details>

### API Key

SRE.ai uses an API Key to configure its Supabase integration.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn about connecting Supabase to SRE.ai</strong></mark></summary>

Connecting to Supabase requires three items:

* Integration Name
* Project URL
  * Found in Dashboard → Settings → API
* API Key
  * [Read Supabase's documentation](https://supabase.com/docs/guides/api/api-keys) to learn about API keys
* Default Schema (Optional)

</details>


# Pipelines

Learn about SRE.ai's Pipelines feature

## Overview

The **pipeline** is what turns your connected **Salesforce orgs** and **GitHub repositories** into a governed **deployment workflow**.

It defines the **stages** a change must pass through (from development to production) and the **quality criteria** each stage enforces.

Without a **pipeline**, SRE.ai has no structure for how code should move through your **environments** or when a **deployment** should be blocked.

Pipelines gives you a **workflow builder** for mapping how code moves from development through production.

Each pipeline is rooted in a **repository** and consists of **stages**, each mapped to a **branch** and one or more **Salesforce environments**.

{% hint style="info" %}
**Pipelines' functionality is informed by best practices for release management.**\
\
[Read SRE.ai's release strategies documentation](/best-practices/release-management-strategies) for more information.
{% endhint %}

## Core capabilities

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FgUVdwvPjY2rjaK2PzDLq%2FScreenshot%202026-01-28%20at%206.03.07%E2%80%AFPM.png?alt=media&amp;token=ab111761-1358-46af-af48-f13472465cd0" alt=""><figcaption></figcaption></figure>

### Templates

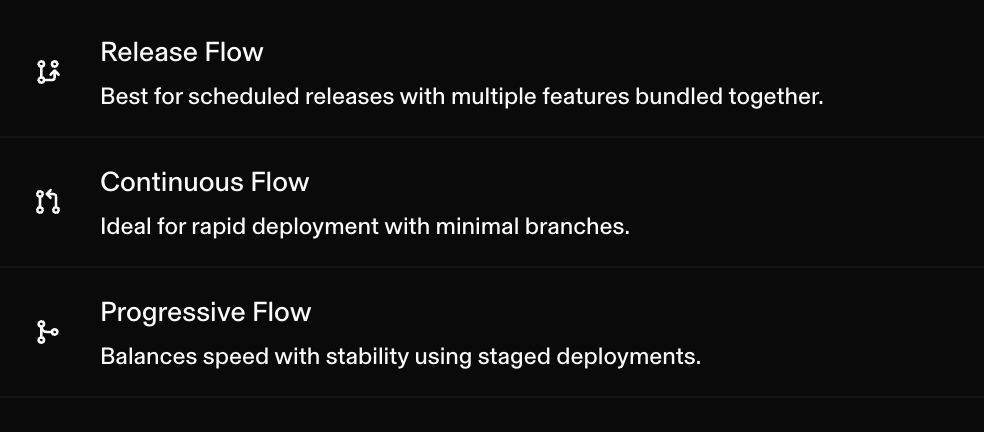
**SRE.ai Pipelines feature offers three preset templates, known as&#x20;*****release management strategies*****:**

* **Release Flow:** Structured, multi-stage promotion with formal QA and a dedicated hotfix path. Best for teams with scheduled release cycles.
* **Progressive Flow:** Multi-stage validation with stricter quality gates at each step. Best for teams that need deliberate control over what reaches production.
* **Continuous Flow:** Simplified, fast path from development to production. Best for teams practicing continuous delivery with rapid iteration.

Templates cannot be edited.

Templates consist of stages.

{% hint style="info" %}
Not sure which template fits your team?

Read [SRE.ai's release strategies documentation](/best-practices/release-management-strategies) for a side-by-side comparison with real-world examples.
{% endhint %}

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2F9lhHSPXTOs3FDDdthD3p%2FScreenshot%202026-02-03%20at%201.50.27%E2%80%AFPM.png?alt=media&amp;token=325fe11f-2d8b-49d3-aa9c-d17c5c5eba82" alt=""><figcaption></figcaption></figure>

### Stages

**A stage is a highly customizable block that represents a discrete phase in your deployment lifecycle.**

{% hint style="success" %}
Each stage serves as both a checkpoint and a configuration point, defining which branch it tracks, which Salesforce environments it deploys to, and the quality standards that must be met before changes can proceed.
{% endhint %}

SRE.ai's Pipelines feature supports five customizable stages:

* developer/ team/ project
* code integration
* staging
* production
* hotfix

The standard Pipelines' progression flows left to right.

An example of a Pipelines' flow:

* **developer/team/project → code integration → staging → production**.

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FqY0x0FF2Gr5QupFN9wNu%2FScreenshot%202026-02-03%20at%201.50.39%E2%80%AFPM.png?alt=media&amp;token=651cdc53-0752-4ba1-a4fc-9c6ffeda0ffa" alt=""><figcaption></figcaption></figure>

### Environments

**Environments are deployment targets within a stage.**

Each environment:

* Maps to a **Salesforce org** (your Production org, Sandbox, or Scratch Org)
* Tracks **deployment status** and history
* Can be **promoted** to parent stage environments

### Salesforce org connections

**Salesforce org connections represent your actual Salesforce organizations that SRE.ai deploys to.**

SRE.ai supports two types of Salesforce orgs connections:

* **Regular Orgs**:
  * Traditional fixed Salesforce orgs (Production or Sandbox) that can be assigned to specific branches.
* **Sandbox Pool Orgs**:
  * Tied to PRs instead of specific branches. These orgs best serve developer workflows.

## How it works

### Template details

Each template creates a fixed stage hierarchy when a pipeline is first configured. The hierarchy determines the only valid promotion path for changes: from child stages up to their parent stage, working toward the root Production stage.

Stages form a tree, not a flat list. Changes must move through every level of the tree in order — skipping stages is not permitted.

* **Release Flow**
  * For scheduled releases with formal QA processes

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn more about the Release Flow template</strong></mark></summary>

{% hint style="success" %}
**Best for**: Teams with scheduled release cycles and formal staging processes.
{% endhint %}

**Stage hierarchy**:

Release Flow is the only template with five stages.&#x20;

Production is the root.&#x20;

Staging and Hotfix are both direct children of Production

Hotfix is a parallel branch off Production, not a step in the main promotion path.&#x20;

Code Integration sits under Staging, and Developer / Team / Project is the leaf under Code Integration.

```
Production (max 1 environment)
├── Staging (no environment limit)
│   └── Code Integration (no environment limit)
│       └── Developer / Team / Project (no environment limit)
└── Hotfix (max 1 environment)
```

**Stages**:

* **Production:**&#x20;
  * Root stage&#x20;
  * Capped at 1 environment
  * All main-flow promotions terminate here
* **Staging:**&#x20;
  * Pre-production validation
  * No environment cap
    * Supports multiple orgs (e.g., UAT and SIT in parallel)
  * Receives promotions from Code Integration.
* **Code Integration:**&#x20;
  * The first shared integration point
  * All developer feature work merges here before advancing to Staging
* **Developer / Team / Project:**&#x20;
  * Leaf stage.&#x20;
  * PR-driven sandbox pool allocation.&#x20;
  * No fixed branch required.
* **Hotfix:**&#x20;
  * Emergency fix path
  * Capped at 1 environment.
  * Direct child of Production, sibling to Staging
  * Changes here promote straight to Production and never pass through Staging or Code Integration

**Default quality gate settings** (apply to all five stages at creation):

* **Code review:**&#x20;
  * Enabled, blocking on Critical-severity comments
* **Code coverage:**&#x20;
  * 75% minimum required to promote
* **Pull requests:**&#x20;
  * Disabled
* **Test level:**&#x20;
  * Run Specified Tests

These defaults apply uniformly. Teams typically tighten gates on Staging and Production and leave Developer stages lighter.

**Promotion paths**:

* Main path:&#x20;
  * Developer / Team / Project → Code Integration → Staging → Production
* Hotfix path:&#x20;
  * Hotfix → Production (bypasses Code Integration and Staging entirely)

</details>

* **Continuous Flow**
  * For rapid deployment and continuous delivery

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn more about the Continuous Flow template</strong></mark></summary>

{% hint style="success" %}
**Best for**: Teams practicing continuous deployment with rapid iteration and minimal promotion overhead.
{% endhint %}

**Stage hierarchy**:

Continuous Flow creates three stages.&#x20;

Production is the root.&#x20;

Staging + Integration is its only child, and Developer / Team / Project is the leaf.

```
Production (max 1 environment)
└── Staging + Integration (no environment limit)
    └── Developer / Team / Project (no environment limit)
```

**Stages**:

* **Production:**&#x20;
  * Root stage.&#x20;
  * Capped at 1 environment.
* **Staging + Integration:**&#x20;
  * Combined integration and pre-production stage.&#x20;
  * `code-integration` stage type.&#x20;
  * No environment cap.
* **Developer / Team / Project:**&#x20;
  * Leaf stage.&#x20;
  * PR-driven sandbox pool allocation.&#x20;
  * No fixed branch required.

**Default quality gate settings** (apply to all three stages at creation):

* **Code review:**&#x20;
  * Enabled, blocking on Critical-severity comments
* **Code coverage:**&#x20;
  * 75% minimum required to promote
* **Pull requests:**&#x20;
  * Disabled
* **Test level:**&#x20;
  * Run Specified Tests

**Promotion path**:

Developer / Team / Project → Staging + Integration → Production

</details>

* **Progressive Flow**
  * For staged validation with enhanced quality gates

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn more about the Progressive Flow template</strong></mark></summary>

{% hint style="success" %}
**Best for**: Teams that want the simplicity of a three-stage layout but intend to configure stricter quality gates and tighter promotion controls than a pure continuous delivery setup.
{% endhint %}

**Stage hierarchy**:

Progressive Flow creates the same three-stage structure as Continuous Flow.&#x20;

The stage names, types, hierarchy, and default settings are identical at the point of creation.

```
Production (max 1 environment)
└── Staging + Integration (no environment limit)
    └── Developer / Team / Project (no environment limit)
```

**Stages**:

* **Production:**&#x20;
  * Root stage.&#x20;
  * Capped at 1 environment.
* **Staging + Integration:**&#x20;
  * Combined integration and pre-production stage.&#x20;
  * `code-integration` stage type.&#x20;
  * No environment cap.
* **Developer / Team / Project:**&#x20;
  * Leaf stage.&#x20;
  * PR-driven sandbox pool allocation.&#x20;
  * No fixed branch required.

**Default quality gate settings** (apply to all three stages at creation):

* **Code review:**&#x20;
  * Enabled, blocking on Critical-severity comments
* **Code coverage:**&#x20;
  * 75% minimum required to promote
* **Pull requests:**&#x20;
  * Disabled
* **Test level:**&#x20;
  * Run Specified Tests

**Promotion path**:

Developer / Team / Project → Staging + Integration → Production

</details>

### How branches map to pipeline stages

Each stage can be configured to connect to a specific branch in your repository.

When you configure a stage, you select which branch it tracks and which Salesforce environment(s) it deploys to.

A typical setup might look like this:

| Stage       | Branch        | Environment(s)               |
| ----------- | ------------- | ---------------------------- |
| Development | `develop`     | Developer sandboxes          |
| Integration | `integration` | QA sandbox                   |
| Staging     | `staging`     | UAT sandbox, SIT environment |
| Production  | `main`        | Production org               |

You can connect multiple Salesforce orgs to a single branch.

As changes move through the pipeline, they can be deployed to one org or several, whichever fits your release process.

{% hint style="info" %}
**Selecting a branch in a pipeline stage doesn't trigger a deployment on its own.**

The branch selection indicates where SRE.ai should look for changes and where to commit metadata.

Deployments happen when you explicitly move changes through the pipeline.
{% endhint %}

### **Deployment workflow**

SRE.ai executes a structured workflow when you initiate a deployment:

1. **Confirm Change**: Verify which change (feature or fix) to deploy
2. **Confirm Target Org**: Auto-detect or select the deployment target based on the stage hierarchy
3. **Check Quality Gates**: Run automated quality checks against stage requirements
4. **Deploy**: Execute deployment to the target Salesforce org if all gates pass
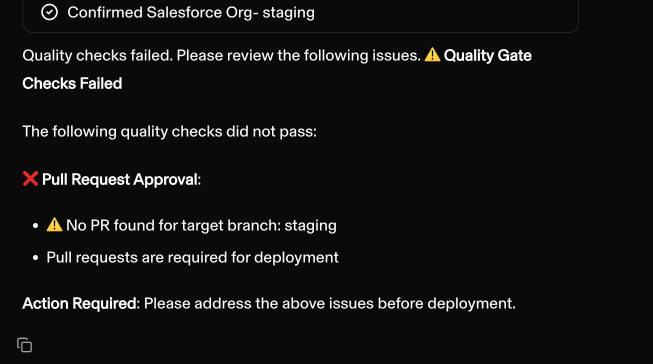
5. **Summarize Issues**: If quality gates fail, provide a detailed issue summary for remediation

This workflow ensures that every deployment meets your quality standards before it is deployed to your Salesforce environments.

### Deployment target enforcement

SRE.ai enforces that changes move through your pipeline **in order**. The deployment target is determined by the pipeline.

{% hint style="info" %}
**Example:** If your pipeline is Developer → Integration → Staging → Production, a change that has only reached Integration can only be promoted to Staging next — not directly to Production.
{% endhint %}

You cannot skip stages or deploy to an out-of-order environment.

* The deployment UI only shows the **next valid target** for a given change. Invalid targets are not available.
* A change's **first deployment** must always target the lowest stage in the pipeline (e.g., Developer or Code Integration).
* Attempting to deploy to an incorrect target returns a clear error.

{% hint style="warning" %}
Deploying to a Salesforce org that is not mapped to a pipeline stage is not supported through the standard deployment flow.

Contact your workspace admin if you need to deploy to an ad-hoc environment.
{% endhint %}

## Setup

### Reset and template selection

A **Reset** button is available in the **top right corner** of the pipeline workspace.

Use it to clear your current pipeline configuration and select a new template. This is useful when starting over or switching release management strategies.

{% hint style="danger" %}
Resetting a pipeline will remove your current stage configuration. This action cannot be undone.
{% endhint %}

To confirm the reset, you will be prompted to type the pipeline name before the action proceeds.

### Initial setup

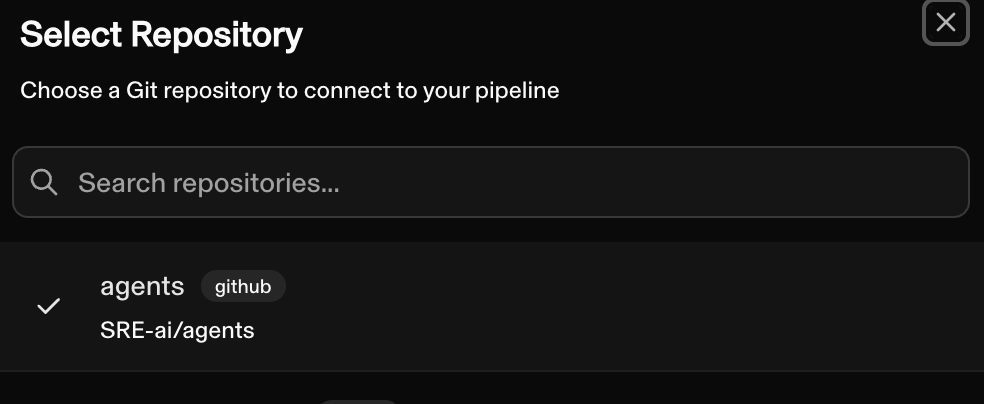
Setting up a pipeline requires two steps:

1. Select a repository to connect to

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FwfSwbEVpbla2BzCC5RPj%2FScreenshot%202026-01-28%20at%206.33.53%E2%80%AFPM.png?alt=media&amp;token=e7b2c815-6dc4-41f0-9359-5c35f24f98e4" alt="" width="563"><figcaption></figcaption></figure>

2. Select a template

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FDYwb8xT17mjU4LEX6zmJ%2FScreenshot%202026-01-28%20at%206.38.47%E2%80%AFPM.png?alt=media&amp;token=a257814c-dbe7-47f4-ac01-932514d0b704" alt="" width="563"><figcaption></figcaption></figure>

### Customization

All five stages share the same customizable attributes:

* Developer/team/project
* Code integration
* Staging
* Production
* Hotfix

Read below to learn about their customizable attributes

<table data-card-size="large" data-view="cards"><thead><tr><th></th></tr></thead><tbody><tr><td><p><strong>Branch association</strong></p><p>Each stage can track a specific Git branch.</p><p>Staging might track a "qa" branch while production tracks "main."<br></p><p>The branch indicator appears in the stage card's upper right corner</p></td></tr><tr><td><p><strong>Environment mapping</strong></p><p>The environments section shows which Salesforce orgs receive deployments when changes reach this stage.<br></p><p>You can search existing environments or add new ones. Multiple environments can be mapped to a single stage for scenarios like parallel QA testing.</p></td></tr><tr><td><p><strong>Quality gates</strong></p><p>Each stage enforces its own set of quality criteria that must be satisfied before changes can advance. Configure code review requirements, code coverage thresholds, test levels, and pull request requirements.</p></td></tr><tr><td><p><strong>Notifications</strong></p><p>Each stage can send notifications to email, Teams, or a webhook destination when specific pipeline events occur, such as deployment success, failure, or a new commit.</p></td></tr></tbody></table>

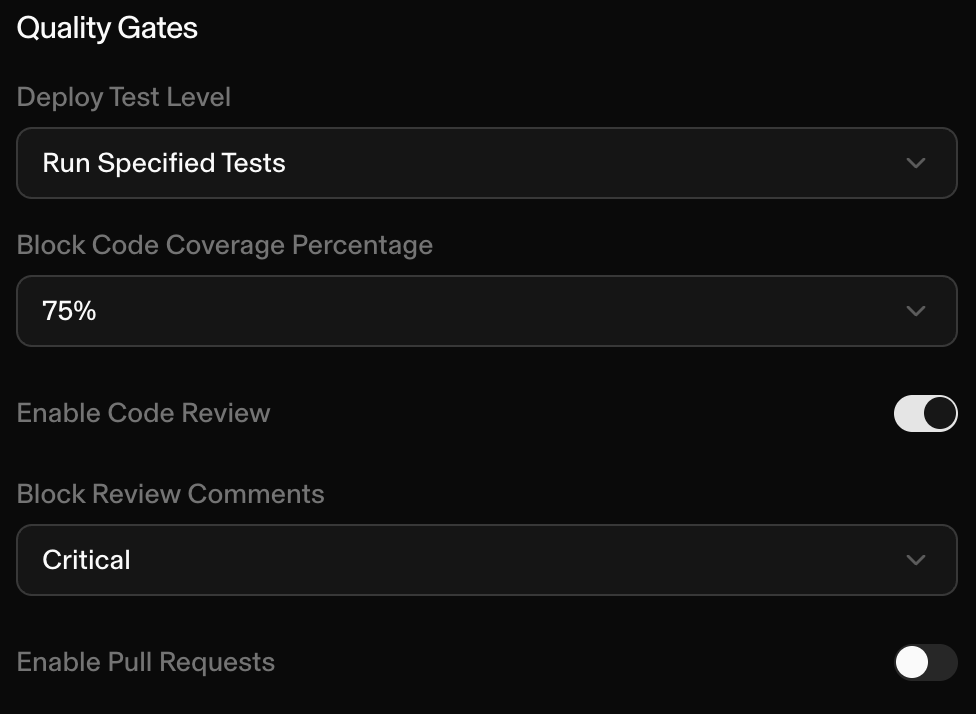
### Quality gates

**Configured at the stage level, quality gates define the criteria that must be satisfied before changes can advance.**

{% hint style="success" %}
Quality Gates are the governance layer that transforms the Pipeline from a visualization tool into an enforcement mechanism.
{% endhint %}

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FtpLaA3jjIoAkbeSQ4QC4%2FScreenshot%202026-01-28%20at%206.02.09%E2%80%AFPM.png?alt=media&amp;token=51c9396c-f2cf-44d6-9ad3-2e955403ca9e" alt="" width="375"><figcaption></figcaption></figure>

Quality gates are enforced when the user attempts to move changes along the pipeline through chat.

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FqqYELBDRG5RVv5Stiz6Q%2FScreenshot%202026-01-28%20at%206.02.49%E2%80%AFPM.png?alt=media&amp;token=a3d34bd8-a2c7-4662-9ef2-387b01a2e52c" alt="" width="490"><figcaption></figcaption></figure>

The following gates are configurable per stage:

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn more</strong></mark></summary>

**Code review**

Enable or disable code reviews for the stage.

When enabled, set the minimum comment severity required to block a deployment: **Critical**, **High**, or **Medium**.

**Code coverage**

Require a minimum code coverage threshold before changes can advance.

Available thresholds: **75%**, **80%**, **85%**, or **90%**.

**Test level**

Control which tests run during a deployment to the stage's environments:

* **Unspecified:** defer to the org's default test behavior
* **No test run:** skip tests entirely
* **Run specified tests:** run only the tests you define
* **Run local tests:** run all tests defined in your package
* **Run all tests in org:** run every test class in the target org

When deploying via chat, the test level inherited from the pipeline stage is shown above the component selection so you can confirm the setting before proceeding.

{% hint style="warning" %}
**No test run is not valid for Production orgs.**

If a stage targets a Production org and no specific tests are configured, SRE.ai automatically falls back to **Unspecified** rather than No test run. Passing a No test run to a Production deployment would cause Salesforce to reject it.

For non-Production orgs (sandboxes), SRE.ai falls back to **No test run** when no tests are specified.
{% endhint %}

**Pull requests**

Require a pull request to be open before changes can advance to this stage.

</details>

### Stage notifications

Each stage can send notifications when pipeline events occur.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn configuration details</strong></mark></summary>

**Platform**

Select where notifications are delivered:

* Email
* Microsoft Teams
* Webhook

**Channel**

Set the specific channel, address, or endpoint that receives the notifications.

**Events**

Enable notifications independently for each of the following events:

* **Initiated:** a deployment to this stage has started
* **Success:** a deployment completed successfully
* **Failure:** a deployment failed
* **Deployment:** any deployment activity
* **Commit:** a new commit was pushed to the tracked branch
* **Change:** a new change was detected in the tracked branch
* **Test failure:** a test run failed during deployment

</details>

### Stage connections

Pipeline connections define how changes move between stages.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn configuration details</strong></mark></summary>

**Merge type**

When changes are promoted, select how they are merged into the target branch:

* **Merge:** Standard merge commit
* **Squash:** Combine all commits into one before merging
* **Rebase:** Rebase commits onto the target branch

**Promotion mode**

* **Automatic:** Changes are promoted without manual intervention when all gates pass
* **Manual:** A user must explicitly trigger the promotion

**Pull requests**

Require a pull request between stages before changes can advance.

**Approvals**

Require at least one approval before changes can advance to the next stage.

</details>


# Roles and permissions

Learn how roles and permissions work in SRE.ai

## Overview

SRE.ai uses role-based access control (RBAC) to manage what team members can do within a workspace.

Every user is assigned one of three roles — **Owner**, **Admin**, or **Member** — which determines what actions they can take across the product, including pipeline management and team settings.

## Roles

SRE.ai defines three roles:

| Role       | Description                                                             |
| ---------- | ----------------------------------------------------------------------- |
| **Owner**  | Full access to all features. Can assign any role to other members.      |
| **Admin**  | Full access except delete operations. Can assign Admin or Member roles. |
| **Member** | Read-only access. Cannot change roles or perform write operations.      |

### Permissions by area

#### Pipelines

| Action                 | Owner | Admin | Member |
| ---------------------- | ----- | ----- | ------ |
| View pipeline          | ✅     | ✅     | ✅      |
| Create / edit pipeline | ✅     | ✅     | ❌      |
| Delete pipeline        | ✅     | ❌     | ❌      |

#### Team settings

| Action                 | Owner | Admin | Member |
| ---------------------- | ----- | ----- | ------ |
| Invite new members     | ✅     | ✅     | ❌      |
| Change a member's role | ✅     | ✅     | ❌      |
| Change own role        | ❌     | ❌     | ❌      |

## Role hierarchy

Role assignment follows a strict hierarchy:

* **Owners** can assign any role (Owner, Admin, or Member) to any other team member
* **Admins** can assign Admin or Member roles, but cannot assign or create Owners
* **Members** cannot assign roles
* No user can change their own role

## Managing roles

### Assigning a role when inviting a new member

1. In the team settings page, click **Invite member**
2. Enter the new member's email address
3. Select a role from the role dropdown — **Owner**, **Admin**, or **Member**
4. Send the invitation

The invited user will be assigned the selected role when they join the workspace.

{% hint style="info" %}
The roles available in the dropdown depend on your own role. Admins will not see the Owner option.
{% endhint %}

### Changing an existing member's role

1. In the team settings page, locate the member in the members list
2. Click the role selector on their row
3. Select the new role

The change takes effect immediately.

{% hint style="warning" %}
You cannot change your own role. Ask another Owner or Admin to make the change if needed.
{% endhint %}


# Chat

Learn about SRE.ai's Chat interface

## Overview

SRE.ai's Chat interface is the primary way to move work through your Salesforce DevOps pipeline.

Chat works in two modes, and you'll use both:

* **Free-form input:** Describe what you need in natural language. SRE.ai routes to the right capability based on intent, no special commands or syntax required.
* **Guided prompts:** At each step, Chat surfaces suggested next actions as clickable options. These tell you what's available from where you are, so you don't need to know what to type to move forward.

Most sessions start free-form: you describe what you're working on and then follow guided prompts through the steps to completion.

## Core capabilities

### Change management via Chat

From Chat, you can:

* **Start a change:** Describe what you want built or modified. SRE.ai creates a Change artifact and tracks it through the full lifecycle.
* **Commit changes:** Persist your Salesforce metadata to the appropriate branch based on your pipeline configuration.
* **Create pull requests:** Generate a PR in your GitHub repository targeting the correct branch for your pipeline stage.
* **Deploy to the next environment:** Advance changes through your pipeline stages with quality gate enforcement before each deployment.
* **Design and build with agents:** Invoke the Design, Build, or Deploy agent directly through Chat for AI-assisted development.

### Deployment intelligence

Before a deployment executes, Chat surfaces the information you need to make a confident decision:

* **Quality gate status:** See whether your change meets the coverage thresholds, static analysis requirements, and PR approvals configured for the target stage.
* **Deployment target confirmation:** Chat identifies the target Salesforce org based on your pipeline stage and asks you to confirm before proceeding.
* **Test level selection:** Choose the test level for the deployment, subject to the governance rules configured in your pipeline (see [Selecting a test level](#selecting-a-test-level)).

### Environment visibility

Chat has awareness of your connected Salesforce orgs and pipeline stages, enabling you to ask questions about:

* The current state of your environments
* What changes are pending or deployed in a given org
* Deployment history for a change or environment

## The change workflow

#### Starting a change

When you create a change in SRE.ai, the platform analyzes the components you're modifying and tracks them against your connected environments.

You'll see test coverage information and an analysis of which metadata types are involved.

#### Committing changes

Once you're ready to persist your work, commit your changes from within SRE.ai.

The platform generates a commit to the appropriate branch based on your pipeline configuration.

#### Creating pull requests

SRE.ai can create pull requests directly from the change interface. When you create a PR:

* The PR is generated in your GitHub repository with your changes
* A link to the PR appears in the SRE.ai change details
* The PR targets the correct branch based on your pipeline stage

You can view and manage the PR either in GitHub or through SRE.ai's interface.

#### Quality gates

Before changes can advance to the next stage, they must pass the quality gates configured for that stage.

Common quality gates include:

* **Pull request approval**
  * A PR must exist and be approved before deployment proceeds. If no PR exists for the target branch, the quality gate fails.
* **Code coverage**
  * Test coverage must meet a configured threshold.
* **Code analysis**
  * Static analysis checks must pass.

Quality gate status appears in the change details panel.

If a gate fails, SRE.ai shows what's blocking deployment and the required actions.

### Deploying to the next environment

After your changes pass quality gates, you can deploy to the next environment in your pipeline.

#### Manual deployment

By default, moving changes through the pipeline requires explicit action.

After committing changes and merging your PR, return to SRE.ai and click **Deploy to next environment** to push the changes to the next stage.

This separation gives you control over timing. Your PR can be merged and ready while you wait for a deployment window or final sign-off.

#### Selecting a test level

{% hint style="info" %}
Test level selection is a gated feature. If you don't see the dropdown, contact your account team to enable it for your workspace.
{% endhint %}

When you initiate a deployment through Chat, a **test level dropdown** appears on the deployment confirmation screen. It defaults to the test level configured in your pipeline stage.

{% hint style="warning" %}
**Test level governance:**

You can only select a test level **equal to or higher** than the level your pipeline stage is configured for. Selecting a lower level is not permitted, pipeline test settings are a governance control and cannot be bypassed through Chat.
{% endhint %}

Available test levels, from lowest to highest:

1. Run Specified Tests / Run Relevant Tests
2. Run Local Tests
3. Run All Tests

If you select a higher test level than your pipeline default (e.g., Run All Tests), a warning will appear noting that this can take longer and will block the pipeline for the team during that window.

{% hint style="info" %}
**Non-Apex deployments:**

If your change contains no Apex components (e.g., only LWC, flows, custom objects, or other non-Apex metadata), SRE.ai automatically applies an appropriate test level and does not require test execution.

The dropdown will reflect this adjustment.
{% endhint %}

#### Deployment failure recovery

If a deployment fails, the chat will automatically surface a **"Fix deployment errors"** suggestion.

Rather than leaving you without a next step, the agent reviews the error output and proposes a resolution.

{% hint style="info" %}
This suggestion only appears when the most recent deployment has failed.

If you don't see it, check the deployment status in the change details panel to confirm whether a failure occurred.
{% endhint %}

#### Automated deployment

If you want deployments to trigger automatically when a PR is merged, you can configure an automation.

Set the trigger to start on PR merge, and the deployment to the next environment kicks off automatically.

This is useful for earlier pipeline stages (development → integration) where you want continuous flow.

For production deployments, most teams prefer the manual approach or add additional approval steps.

{% hint style="info" %}
**TIP:**

You can configure distinct behaviors for each stage.

Automate deployments through your lower environments, but require manual promotion to production.
{% endhint %}

### Syncing branches and orgs

When you first connect a repository, your branch and your Salesforce org may not be in sync.

Metadata might exist in the org but not be reflected in the branch, or vice versa.

#### Initial sync strategies

**Option 1: Push org metadata to a new branch**

The simplest approach is to create a fresh branch and push all metadata from your org into it.

This establishes the branch as the source of truth going forward.

**Option 2: Pull repository contents into the org**

If your branch already contains the canonical version of your metadata, you can configure an automation to pull everything from the repository into your org.

If components exist in the repo but not in the org (or vice versa), SRE.ai flags the discrepancies so you can resolve them.

**Option 3: Identify and reconcile differences**

For more complex situations, SRE.ai can help you understand the differences between your branch and your org.

During onboarding, the team works with you to identify gaps and either automate the sync or handle it manually.

#### Ongoing drift

Over time, orgs and branches can drift apart, especially if changes are made directly in production or if sandbox refreshes introduce discrepancies.

SRE.ai tracks changes across your environments, making it easier to identify out-of-sync items and reconcile differences before they cause deployment issues.

### Viewing changes without source tracking

Even if source tracking isn't enabled on a Salesforce environment, you can still see what's changed.<br>

SRE.ai's **View My Changes** feature shows all changes made in an org, not just recent ones, but also historical changes.

To access this:

1. Navigate to the org in question (even without a connected repo)
2. Open **View My Changes**
3. Filter by component type, date range, or other criteria

This is useful for auditing environments, understanding what's deployed where, and identifying changes that need to be captured in source control.

{% hint style="danger" %}
**IMPORTANT:**

Source tracking speeds up and improves the precision of change detection.\
\
SRE.ai can still surface changes without source tracking, but enabling source tracking is recommended for the best experience.
{% endhint %}

## Prompts and changes

Click below to view a collection of optimized prompts and learn how to track and manage changes.

<table data-card-size="large" data-view="cards"><thead><tr><th></th><th data-hidden data-type="content-ref"></th><th data-hidden data-card-target data-type="content-ref"></th></tr></thead><tbody><tr><td><strong>How to talk to SRE.ai</strong></td><td><a href="/using-sre.ai/command-center/prompt-library">Prompt library</a></td><td><a href="/using-sre.ai/command-center/how-to-talk-to-sre-ai">How to talk to SRE.ai</a></td></tr><tr><td><strong>Changes</strong></td><td><a href="/using-sre.ai/changes">Changes</a></td><td><a href="/using-sre.ai/changes">Changes</a></td></tr></tbody></table>


# How to talk to SRE.ai

Learn how to phrase requests effectively in SRE.ai's Chat interface

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FDS2UjTA3uRft476wEt8H%2FPre-Made%20Prompts.png?alt=media&amp;token=45e7dcd7-b6e3-49d4-afc2-a61c30be5861" alt=""><figcaption></figcaption></figure>

SRE.ai's Chat works in two modes.

You start in **free-form,** describe what you're working on in your own words, no special syntax required.&#x20;

From there, Chat surfaces **suggested prompts** as clickable options at each step, guiding you forward without requiring you to know what to type next.

The first message is yours. The path forward is offered.

This guide covers both: what to type when you're getting started, and what to expect as Chat guides you through.

## How to read the transcripts in this guide

Conversations in SRE.ai involve two kinds of user input:

* **Typed input:** you write your own message in the text field
* **Suggested prompt:** Chat surfaces a clickable option and you select it

In the transcripts below, suggested prompts are marked like this:

> *Chat suggested: "Design a solution"*\
> **You:** Design a solution

The distinction matters because it shows when you're navigating freely and when the product is guiding you.

## Starting a change

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FGARZe2UnUKOvd0t1K3lE%2FIn-Chat%20Prompts.png?alt=media&amp;token=05033b35-df04-4d03-ba30-db8791aee29f" alt=""><figcaption></figcaption></figure>

A Change is SRE.ai's unit of work.&#x20;

You always start one with free-form input, describe what you're working on, and SRE.ai creates a Change to track it through the full lifecycle.

**You** *(typed)*: I need to add a validation rule on the Account object that prevents saving if the Phone field is empty when the record type is Partner.

**SRE.ai:** Got it. I've created a Change for this.

> *Chat suggested: "Design a solution" · "Build directly"*

{% hint style="info" %}
After creating a Change, Chat surfaces two paths: invoking the Design Agent to produce a technical spec first, or invoking the Build Agent directly for simpler tasks.&#x20;

You can click a suggestion or type your own direction, both work.
{% endhint %}

**You could also type:**

* "Create a change for adding a validation rule to Account"
* "We need a validation rule on Account — Phone required for Partner record type"
* "There's a bug: Partner accounts can save without a phone number"

All three land in the same place.&#x20;

The more context you include upfront (the object, the condition, the expected behavior) the less back-and-forth the agent needs before it starts.

## Working with agents

Agents handle the design and implementation work.&#x20;

The typical flow is: describe → design → approve → build.

### Invoking the Design Agent

> *Chat suggested: "Design a solution"*\
> **You:** Design a solution

**SRE.ai:** Starting the Design Agent. I'll explore your repository and the Account object metadata, then produce a design document for your review.

*\[Agent researches repository patterns and Salesforce metadata]*

**SRE.ai:** Design document ready. I'm proposing a standard Salesforce validation rule using an `ISPICKVAL` formula. The document includes success criteria, implementation steps, and a testing strategy. Ready for your review.

{% hint style="info" %}
You don't need to click the suggestion, you can type "design a solution for...," "let's think through this first," or "create a spec for..." and the Design Agent activates. SRE.ai routes based on intent, not syntax. The suggested prompt is a shortcut, not a requirement.
{% endhint %}

### Approving a design and building

After reviewing the design document, you approve it and move to implementation.

> *Chat suggested: "Build this"*\
> **You:** Build this

**SRE.ai:** Starting the Build Agent. I'll use the dev sandbox as the target instance — is that correct?

**You** *(typed)*: Yes.

**SRE.ai:** Building. I'll create a feature branch, implement the validation rule, validate, and commit the result.

*\[Agent creates branch, implements, validates, and commits]*

**SRE.ai:** Done. The validation rule has been implemented, validated, and committed to a feature branch. Ready to create a pull request?

{% hint style="info" %}
The Build Agent always confirms the target instance before it starts. This is a human-in-the-loop checkpoint, you can redirect to a different org if the one it selects isn't right.
{% endhint %}

## Moving a change through the pipeline

Once work is on a feature branch, Chat guides you through the commit, PR, and deployment steps.

### Creating a pull request

> *Chat suggested: "Create a pull request"*\
> **You:** Create a pull request

**SRE.ai:** Creating a pull request in your GitHub repository, targeting the integration branch based on your pipeline configuration.

*\[PR created]*

**SRE.ai:** PR created. You can review it in GitHub or from the Change detail view here.

### Deploying to the next environment

> *Chat suggested: "Deploy to next environment"*\
> **You:** Deploy to next environment

**SRE.ai:** Before I deploy, here's what I'm seeing:

* **Target:** Integration sandbox (next stage in your pipeline)
* **Quality gates:** PR approval ✓ · Code coverage 82% ✓ · Static analysis ✓
* **Test level:** Run Local Tests (pipeline default)

Confirm deployment?

> *Chat suggested: "Yes, deploy"*\
> **You:** Yes, deploy

**SRE.ai:** Deploying to Integration. I'll run local tests and report back.

{% hint style="info" %}
SRE.ai always surfaces the deployment target, quality gate status, and test level before executing. This gives you one place to confirm that everything is correct, you don't need to check these separately.
{% endhint %}

### Overriding the test level

If you want to run a higher test level than the pipeline default, type it rather than clicking the suggestion.

**You** *(typed)*: Deploy to next environment, but run all tests this time.

SRE.ai will apply **Run All Tests** if your pipeline governance permits it. You can only select a level equal to or higher than the pipeline default, governance rules can't be bypassed through Chat.

{% hint style="warning" %}
Running a higher test level than the pipeline default will take longer and block the pipeline for your team during that window. SRE.ai will surface a warning before you confirm.
{% endhint %}

## When something goes wrong

### Deployment failure

If a deployment fails, SRE.ai surfaces the error and offers a path forward without you having to ask.

**SRE.ai:** Deployment to Integration failed. Here's what happened: \[error summary]

> *Chat suggested: "Fix deployment errors"*

**You:** Fix deployment errors

**SRE.ai:** Reviewing now. I'll propose a resolution before making any changes.

{% hint style="info" %}
The "Fix deployment errors" prompt only appears when the most recent deployment has failed. If you don't see it, check the deployment status in the Change detail panel to confirm a failure occurred.
{% endhint %}

## What SRE.ai needs from you

Guided prompts handle most of the navigation.&#x20;

Free-form input is where context matters most, specifically when starting a change or invoking an agent.

Three things help:

**The object or component.** "The Account object," "the Case Type picklist," "the OpportunityLineItem trigger", naming what's involved saves a round-trip.

**The condition or behavior.** "When the record type is Partner," "after a successful deployment," "if the field is empty", context shapes the solution.

**The intended outcome.** "Should prevent saving," "should commit to the feature branch," "should run all tests", stating what you want, not just what's broken.

You don't need all three every time. Once a Change is underway, the guided prompts carry most of the work forward. Free-form input is most valuable at the start, when the agent needs to understand what it's building.


# Prompt library

Browse optimized prompts for common use cases

<table data-card-size="large" data-view="cards"><thead><tr><th></th><th></th></tr></thead><tbody><tr><td><img src="https://a.slack-edge.com/production-standard-emoji-assets/14.0/apple-medium/1f527.png" alt=":wrench:"> <strong>Troubleshooting / Debugging</strong></td><td><ul><li>"Why is my integrated-dev deployment failing with a profile merge conflict?”</li><li>“Check if there are Apex test failures in the last UAT deployment.”</li><li>“Find out which managed package is conflicting with our custom code.”</li><li>“Show me the error logs that repeat in the last 3 deployment runs.”</li></ul></td></tr><tr><td><img src="https://a.slack-edge.com/production-standard-emoji-assets/14.0/apple-medium/1f680.png" alt=":rocket:"> <strong>Deployment &#x26; CI/CD</strong></td><td><ul><li>"Deploy the latest changes from <code>feature/login</code> into the QA sandbox.”</li><li>“Promote recent changes from QA to UAT.”</li><li>“Rollback the last deployment to dev.”</li><li>“Compare main branch with UAT and list differences in the Segment Opportunity flow.”</li><li>“Run seeded-data tests before promoting to staging.”</li><li>“Schedule a deployment for tomorrow at 10am PST.”</li></ul></td></tr><tr><td><img src="https://a.slack-edge.com/production-standard-emoji-assets/14.0/apple-medium/1f4ca.png" alt=":bar_chart:"> <strong>Data &#x26; Metadata Management</strong></td><td><ul><li>“Migrate 500 sample Accounts and Contacts into the dev sandbox.”</li><li>“Sync picklist values from production to QA.”</li><li>“Show me all fields added to my custom objects in the last 7 days.”</li><li>“Which objects in my prod instance have changed since the last release?”</li><li>“Copy configurations from the finance SAP client to test client.”</li></ul></td></tr><tr><td><img src="https://a.slack-edge.com/production-standard-emoji-assets/14.0/apple-medium/1f50d.png" alt=":mag:"> <strong>Knowledge &#x26; Insights</strong></td><td><ul><li>“Explain what this deployment error means: <code>Duplicate field: Email__c</code>.”</li><li>“Summarize changes in the last 5 deployments.”</li><li>“Show me known risks with enabling Person Accounts.”</li><li>“What’s the difference between Apex classes and triggers in terms of deployment order?”</li></ul></td></tr><tr><td><img src="https://a.slack-edge.com/production-standard-emoji-assets/14.0/apple-medium/1f6e0-fe0f.png" alt=":hammer_and_wrench:"> <strong>Environment &#x26; Infra Management</strong></td><td><ul><li>“Spin up a new Salesforce QA environment with sample data.”</li><li>“Clone UAT into a temporary sandbox for hotfix testing.”</li><li>“Tear down the unused dev sandbox after exporting configs.”</li><li>“Show current environments and their last refresh dates.”</li></ul></td></tr><tr><td><img src="https://a.slack-edge.com/production-standard-emoji-assets/14.0/apple-medium/1f9fe.png" alt=":receipt:"> <strong>Audit &#x26; Compliance</strong></td><td><ul><li>“Who approved the last deployment into production?”</li><li>“Show all deployments made this month with status.”</li><li>“Export an audit report of schema changes.”</li><li>“List users who pushed directly to prod in the last 30 days.”</li><li>“Which deployments had test coverage below 75%? Give suggestions for improving coverage”</li></ul></td></tr></tbody></table>


# Agents

Learn about SRE.ai's agentic capabilities

## Overview

Agents are chat-based assistants that execute complex tasks.

{% hint style="success" %}
Rather than navigating menus or configuring settings, users describe their needs in the chat interface, and the appropriate agent takes action.
{% endhint %}

Each agent is powered by a specialized LLM trained on Salesforce development patterns, best practices, and platform-specific constraints.

## How Agents work

### Activation

Agents are invoked through the chat interface based on intent.

{% hint style="success" %}
There are no special commands or syntax. Describe what you need, and SRE.ai routes to the appropriate agent.
{% endhint %}

**Examples:**

* "I need to implement a regression test class for the Case Type picklist" → Design Agent
* "Let's build this" (after a design is approved) → Build Agent
* "Deploy these changes to staging" → Deploy Agent

### Visibility

Agents surface every action they take.

When an agent executes, users see:

* **Thought process:** The agent's reasoning as it plans the work
* **Plan:** A structured list of steps the agent will execute
* **Step-by-step progress:** Each action logged with timestamps
* **Artifacts:** Design documents, code files, PRs, and other outputs

Users can expand any step to see details, including commands run, files read, and web searches performed.

### Human-in-the-loop

Agents pause at key decision points for user input:

* Design documents require approval before building begins
* Generated code is presented for review before committing
* Deployments surface what will change before executing

This ensures users maintain control over what gets created and deployed.

### Execution environment

Each agent task runs in an isolated, ephemeral container. Containers are pre-warmed, so agents start in under a second.

Every task gets a clean environment.

There is no state carried over from previous runs. This makes agent results reproducible and prevents unintended side effects between tasks.

Operations have defined time limits:

| Operation                  | Timeout    |
| -------------------------- | ---------- |
| Generate code (Apex, etc.) | 5 minutes  |
| Run code                   | 5 minutes  |
| Commit change              | 10 minutes |
| Review change              | 10 minutes |
| Retrieve metadata          | 30 minutes |
| Deploy metadata            | 2 hours    |

If an operation exceeds its limit, the task will fail with a timeout error.

For complex deployments or large metadata retrievals, this is the expected constraint to be aware of.

### Integration with Changes

Agent work ties back to SRE.ai's Changes feature.

When an agent begins work, it creates or links to a Change artifact that tracks the full lifecycle, from design through deployment. This provides a single view of everything associated with a feature or fix.

Agents can also link to external issue trackers. If a Jira ticket is referenced, the agent associates its work with that issue. However, linked tickets are not required. Users can simply describe their requirements.

## Agent summaries

### Design agent

The Design Agent creates technical design documents for Salesforce development work.

<table data-card-size="large" data-view="cards"><thead><tr><th></th><th></th></tr></thead><tbody><tr><td><p><strong>What it does</strong></p><p>Given a problem statement or feature request, the Design Agent:</p><ul><li>Explores your repository structure and existing patterns</li><li>Examines relevant Salesforce metadata (objects, fields, picklists, etc.)</li><li>Research best practices and validation requirements</li><li>Designs a solution architecture</li><li>Produces a comprehensive technical design document</li></ul></td><td></td></tr><tr><td><p><strong>Output</strong></p><p>The Design Agent generates a design document that includes:</p><ul><li><strong>Success criteria:</strong> What the implementation must achieve</li><li><strong>Architecture:</strong> Component overview and relationships</li><li><strong>Design decisions:</strong> Rationale for the chosen approach</li><li><strong>Implementation plan:</strong> Steps to build the solution</li><li><strong>Testing strategy:</strong> How the solution will be validated</li><li><strong>Risks:</strong> Potential issues and mitigations</li></ul><p>Design documents are stored in the Change artifact. Each document has a status that tracks where it is in the review process:</p><p>You can change the status at any time using the status selector in the document header. The document content is editable and saves automatically.</p></td><td></td></tr><tr><td><p><strong>Example</strong></p><p><strong>User:</strong> "Implement a regression test class for the value in Type picklist"</p><p><strong>Design Agent actions:</strong></p><ol><li>Confirms the issue and creates a Change</li><li>Explores repository structure and patterns</li><li>Examines the Case object and the Type picklist metadata</li><li>Research picklist validation best practices</li><li>Designs the test architecture</li><li>Creates a comprehensive technical design document</li><li>Submits design for approval</li></ol><p><strong>Output:</strong> A design document specifying that the solution will use Salesforce's Schema API to dynamically retrieve and validate picklist metadata, with success criteria including 100% code coverage and immediate failure when required values are missing.</p></td><td></td></tr><tr><td><p><strong>Steps</strong></p><ol><li>Describe the problem or feature in the chat interface</li><li>The Design Agent confirms the issue and creates a linked Change</li><li>Review the agent's plan via "View Plan"</li><li>Monitor progress as the agent researches and designs</li><li>Review the generated design document</li><li>Approve the design to proceed to building, or request revisions</li></ol></td><td></td></tr></tbody></table>

### Build agent

The Build Agent implements solutions based on approved designs or direct instructions.

<table data-card-size="large" data-view="cards"><thead><tr><th></th></tr></thead><tbody><tr><td><p><strong>What it does</strong></p><p>Given an approved design or a build request, the Build Agent:</p><ul><li>Initializes the repository context</li><li>Creates a feature branch from main</li><li>Generates code files following your repository's patterns</li><li>Creates associated metadata files</li><li>Deploys and validates in a target instance</li><li>Commits and pushes changes</li></ul></td></tr><tr><td><p><strong>Output</strong></p><p>The Build Agent produces:</p><ul><li><strong>Feature branch:</strong> A new branch for the implementation</li><li><strong>Code files:</strong> Apex classes, Lightning components, or other artifacts</li><li><strong>Metadata files:</strong> Associated .meta.xml files configured correctly</li><li><strong>Validation results:</strong> Confirmation that code deploys and tests pass</li><li><strong>Committed changes:</strong> Code pushed to the feature branch</li></ul><p>All generated code follows existing repository patterns. The agent examines your codebase to match naming conventions, file organization, and coding style.</p></td></tr><tr><td><p><strong>Example</strong></p><p><strong>User:</strong> "Let's build this" (after approving a design for a regression test class)</p><p><strong>Build Agent actions:</strong></p><ol><li>Confirms target instance (e.g., poolorg01)</li><li>Implements solution per the design document</li><li>Creates feature branch (e.g., feature/d9c96ea9) from main</li><li>Creates CaseTypePicklistTest.cls file</li><li>Creates CaseTypePicklistTest.cls-meta.xml file</li><li>Deploys and validates test class</li><li>Commits and pushes changes</li></ol><p><strong>Output:</strong> A complete, validated implementation on a feature branch ready for review.</p></td></tr><tr><td><p><strong>Steps</strong></p><ol><li>Approve a design document, or describe what you want built directly</li><li>The Build Agent confirms the target instance</li><li>Review the agent's plan via "View Plan"</li><li>Monitor progress as the agent creates and validates code</li><li>Review the generated files and validation results</li><li>Proceed to PR creation or request changes</li></ol></td></tr></tbody></table>

### Deploy agent

The Deploy Agent handles AI-driven deployments to target environments.

<table data-card-size="large" data-view="cards"><thead><tr><th></th></tr></thead><tbody><tr><td><p><strong>What it does</strong></p><p>Given a deployment request, the Deploy Agent:</p><ul><li>Identifies what needs to be deployed</li><li>Confirms the target environment</li><li>Executes the deployment with appropriate validations</li><li>Reports results and surfaces any issues</li></ul></td></tr><tr><td><p><strong>Output</strong></p><p>The Deploy Agent produces:</p><ul><li><strong>Deployment confirmation:</strong> What was deployed and where</li><li><strong>Validation results:</strong> Test execution and quality gate status</li><li><strong>Error reporting:</strong> Clear surfacing of any failures with context</li></ul></td></tr><tr><td><p><strong>Example</strong></p><p><strong>User:</strong> "Deploy these changes to staging"</p><p><strong>Deploy Agent actions:</strong></p><ol><li>Identifies the changes to deploy</li><li>Confirms staging as the target environment</li><li>Executes deployment</li><li>Runs associated validations</li><li>Reports success or surfaces issues</li></ol><p><strong>Output:</strong> Deployed changes with validation results, logged in the Change timeline.</p></td></tr><tr><td><p><strong>Steps</strong></p><ol><li>Describe what you want deployed and where</li><li>The Deploy Agent confirms the target and scope</li><li>Review the deployment plan</li><li>Monitor progress as the agent deploys and validates</li><li>Review results in the Command Center</li></ol></td></tr></tbody></table>


# Changes

Learn how to track and manage changes in SRE.ai

## Overview

A Change is SRE.ai's core unit of work.

It tracks everything associated with a feature or fix, from the initial description through code commits, pull requests, and deployment across environments.

Changes support every metadata type supported by the Metadata API.

Usually, developing a new feature in Salesforce involves updating a range of metadata types and data.

Tasks, Apex scripts, and manual steps may also be involved.

{% hint style="info" %}
You can import changes directly if your source environment is enabled for Source Tracking.
{% endhint %}

## **Core capabilities**

### Change lifecycle

A Change moves through your deployment pipeline as work progresses.

SRE.ai tracks the current stage automatically based on deployment history.

If new commits have been added since the last successful deployment, the change is flagged as needing re-deployment.

Each change has a status:

* **Active:** The change is in progress
* **Archived:** The change has been completed or closed

### What a Change tracks

#### Commits

Every git commit associated with a change is linked and visible in the change view.

Commits are scoped to a specific branch, which SRE.ai creates automatically if one is not provided.

#### Pull requests

Pull requests created from a change branch are automatically associated with the change. For each PR, SRE.ai tracks:

* **Review status**: Pending, Approved, Changes Requested, or Commented
* **Merge state**: Open, Merged, or Closed
* Who last reviewed it and when
* Who merged it and when

#### Data queries

Changes can include SOQL queries that define data to retrieve alongside the metadata.

When present, these queries are saved as reusable templates and appear as selectable options in the commit tool, so the same query can be applied across multiple commits without re-entering it.

## **How it works**

### Deployments

Each deployment of a change to a Salesforce environment is recorded, including which commit was deployed, which stage it targeted, and whether it succeeded.

### Code quality

SRE.ai runs code analysis on the files modified by a change and surfaces findings directly in the change view.

**Finding types:**

| Type                       | Description                                                           |
| -------------------------- | --------------------------------------------------------------------- |
| Static code analysis       | Rule-based violations (e.g., PMD, ESLint) with severity and rule name |
| AI analysis                | AI-generated observations about code quality, patterns, and risks     |
| Dependency reference check | Checks for broken or missing references across metadata components    |

**Finding severity:** Critical, High, Medium, Low, Info

**Finding statuses:**

* **Open:** New or unresolved
* **In progress:** Being worked on
* **Resolved:** Fixed and closed
* **Dismissed:** Marked as not applicable

Users can provide feedback on findings (positive or negative) and leave comments. Findings can also be marked as implemented once a fix has been deployed.

**PR and MR comments**

When a pull request or merge request is linked to a change, SRE.ai automatically posts code findings as inline comments so reviewers see them without leaving the code review.

* **GitHub:** Findings are submitted as a single pull request review with one inline comment per finding, anchored to the specific file and line number.
* **GitLab:** Findings are posted as MR discussions. Each comment includes the file path and line number in the body.

Which findings are posted:

* **Severity:** Critical, High, and Medium only. Low and Info are not posted
* **Status:** Open and In Progress only. Resolved and Dismissed findings are excluded
* **Cap:** Up to 50 comments per PR/MR
* **Deduplication:** Findings that were already commented on are not reposted when a PR is updated

{% hint style="info" %}
Findings are only posted for files that appear in the pull request diff. If a finding references a file not changed in the PR, that comment is skipped.
{% endhint %}

### Test coverage

For Apex code, SRE.ai tracks test coverage at the class level. Each change shows:

* Overall coverage percentage vs. the required threshold
* Which lines are covered and which are not
* A per-class breakdown with test method detail

### Activity timeline

The timeline logs every significant event in a change's lifecycle:

* Change created or updated
* Commit added
* Deployment completed
* Pull request created, reviewed, or merged

Each entry includes a timestamp and the user who performed the action.

### External issues

Changes can be linked to Jira or Linear issues.

When a change is updated, SRE.ai automatically syncs the relevant fields back to the linked issue, keeping your issue tracker up to date without manual updates.

Links to external issues are visible in the change header and can be added or removed at any time.

## Setup

The Changes page lists all changes in your workspace.

Each change row displays a **component count badge** (e.g., "3 components") so you can gauge the scope of a change at a glance without opening it.

The view can be filtered and adjusted:

* **Status filter**: Active or Archived
* **Visible columns**: Status, Source Org, Stage, Created, Last Updated
* **Rows per page**: 10, 20, 30, 50, or 100

Click on any change to expand its details and adjust the Change.


# Automations

Learn about SRE.ai's Automations feature

## Overview

**Automations** let you define and orchestrate **multi-step workflows** across your DevOps pipeline.

An Automation is a sequence that runs automatically when a specific event happens.

You define a sequence once, and SRE.ai runs it for you.

Each Automation has two parts:

* A **Trigger** defines what kicks it off
* **Steps** define what happens next, in order

{% hint style="success" %}
You define the goal. Automations handle the how.
{% endhint %}

## **Core capabilities**

### **Triggers**

Triggers initiate an Automation.

Triggers allow you to initiate an Automation exactly when needed, whether it's:

* After a **manual activation**
* After a **deployment** completes

{% hint style="success" %}
Learn more about Triggers in[ SRE.ai's Triggers documentation](/using-sre.ai/automations/triggers).
{% endhint %}

### **Steps**

Steps define the execution of an Automation

Steps let you define the sequence of instances and dependencies that occur after a Trigger.

You can also define conditions and criteria to keep each Step's execution smooth and error-free.

{% hint style="success" %}
Learn more about Steps in [SRE.ai's Steps documentation](/using-sre.ai/automations/steps).
{% endhint %}

### Comprehensive workflow support

Combining Triggers and Steps allows you to customize your workflows to meet your specific needs.

Here are some functions you can execute with combinations of Triggers and Steps:

* Promote changes when a pull request is approved
* Automatically update a Jira issue when you promote a change to an environment
* Enable continuous integration and continuous deployment
* Create and install package versions based on git operations
* Maintain a pool of scratch orgs with up-to-date packages, data, and configurations
* Notify your team by posting messages to Microsoft Teams channels directly from your workflows

{% hint style="info" %}
**Salesforce connection support:** Automations work with both OAuth and JWT-authenticated Salesforce connections.
{% endhint %}

## **How it works**

### Main page

By default, the Automations page only displays active Automations.

**Click the "All" button** to view every Automation in your system.

**Click on an existing Automation** to view or edit the Automation.

### Activity tab

The Activity tab in the Automation Builder displays the history of the given Automation.

### Stopping an Automation

To stop a running Automation, open the Activity tab and click the **Stop** button next to the active run.

This is useful for canceling hung or unintended Automation executions.

## Setup

1. **Click the "New" button** on the main page to open the Automation Builder, where you can name your Automation.
2. In the Automation Builder, click **the Edit button** to add or remove Steps and edit existing Triggers and/or Steps.
3. Click **the Activation button** to activate your Automation after you have arranged your desired Triggers and Steps.
4. Automations will handle the rest, ensuring your processes run smoothly and efficiently.


# Triggers

Learn about Triggers for Automations

## What are Triggers?

Triggers are the entry points to an Automation in SRE.ai.

Triggers initiate Automations once their specific event occurs.

{% hint style="success" %}
Triggers help you respond automatically to DevOps activity without polling, scripts, or brittle automations.
{% endhint %}

## Available Triggers

SRE.ai offers two Trigger types:

* **Manual:** Activated by clicking a button in the Automations Builder
* **Deployment:** Activated when a deployment completes

## How Triggers work

**Click on a Trigger in the Automations Builder** to open the Trigger panel and select or change the Trigger type.


# Triggers customization

Learn about the customizable parameters in each Trigger

## Overview

SRE.ai offers two Triggers:

* [Manual](#manual-trigger-customization)
* [Deployment](#deployment-trigger-customization)

Read below to learn about the parameters that can be customized within each Trigger.

## Manual trigger customization

A click activates a manual trigger.

The manual trigger features one customizable parameter, a **Description.**

## Deployment trigger customization

The deployment trigger fires automatically when a deployment in your pipeline reaches a terminal state (success or failed).

**Parameters**

| Field             | Description                                                                          |
| ----------------- | ------------------------------------------------------------------------------------ |
| **Description**   | Optional label describing when this trigger fires                                    |
| **Org filter**    | Limit to specific Salesforce orgs. If empty, the trigger fires for all orgs          |
| **Status filter** | Limit to `success`, `failed`, or both. If empty, the trigger fires on either outcome |

**Available trigger data**

When a deployment trigger fires, the following variables are available to all steps in the Automation via `{{trigger_data.*}}` syntax:

| Variable                                | Description                                  |
| --------------------------------------- | -------------------------------------------- |
| `{{trigger_data.deployment_id}}`        | ID of the deployment that fired the trigger  |
| `{{trigger_data.deployment_status}}`    | Outcome: `success` or `failed`               |
| `{{trigger_data.org_id}}`               | ID of the target Salesforce org              |
| `{{trigger_data.org_name}}`             | Display name of the target org               |
| `{{trigger_data.components_total}}`     | Total number of components in the deployment |
| `{{trigger_data.components_succeeded}}` | Number of components deployed successfully   |
| `{{trigger_data.components_failed}}`    | Number of components that failed             |
| `{{trigger_data.tests_total}}`          | Total test count (Apex deployments only)     |
| `{{trigger_data.tests_succeeded}}`      | Tests that passed (Apex deployments only)    |
| `{{trigger_data.tests_failed}}`         | Tests that failed (Apex deployments only)    |
| `{{trigger_data.failure_count}}`        | Number of failures (if any)                  |
| `{{trigger_data.failure_summary}}`      | Summary of up to 3 failure messages (if any) |

**Example: notify on failure**

Use trigger data in a Send Teams Message step to build a context-aware alert:

```
Deployment to {{trigger_data.org_name}} {{trigger_data.deployment_status}}.
Components: {{trigger_data.components_succeeded}}/{{trigger_data.components_total}} succeeded.
{{trigger_data.failure_summary}}
```


# Steps

Learn about Steps for Automations

## What are Steps?

Steps are the actions that your Automation performs after being triggered.

{% hint style="success" %}
You can string multiple Steps together to create powerful, rule-based automations across your DevOps pipeline.
{% endhint %}

## Available Steps

SRE.ai offers nine Step types:

* [Create Salesforce Change](/using-sre.ai/automations/steps/steps-customization#create-salesforce-change-setup-and-customization)
* [Commit Change](/using-sre.ai/automations/steps/steps-customization#commit-change-setup-and-customization)
* [Deploy Package](/using-sre.ai/automations/steps/steps-customization#deploy-package-setup-and-customization)
* [Send Teams Message](/using-sre.ai/automations/steps/steps-customization#send-teams-message-setup-and-customization)
* [Create Scratch Org](/using-sre.ai/automations/steps/steps-customization#create-scratch-org-setup-and-customization)
* [Generate Seed Data](/using-sre.ai/automations/steps/steps-customization#generate-seed-data-setup-and-customization)
* [Load Seed Data](/using-sre.ai/automations/steps/steps-customization#load-seed-data-setup-and-customization)
* [Insert into Supabase](/using-sre.ai/automations/steps/steps-customization#insert-into-supabase-setup-and-customization)
* [Update Jira Ticket](/using-sre.ai/automations/steps/steps-customization#update-jira-ticket-setup-and-customization)

## How Steps work

### Adding or deleting Steps

In the **Automations Builder,** **select the Edit Automations icon to add or delete Steps**.

### Editing existing Steps

**Click any Step** in an Automation **to open the View Step panel**

**Click the Edit button** in **the top right of the View Step panel to edit the Step's parameters**.

### Customization

Each Step features customizable parameters.

Learn more about the customizable parameters for each Step by reading[ SRE.ai's Steps customization documentation](/using-sre.ai/automations/steps/steps-customization).


# Steps customization

Learn about the customizable parameters in each Step

## Overview

SRE.ai offers nine Step types:

* **Create Salesforce Change:** Open a new Change to track metadata updates
* **Commit Change:** Retrieve metadata from a Salesforce org and commit it to Git
* **Deploy Package:** Deploy committed metadata to a target Salesforce org
* **Send Teams Message:** Post a notification to a Microsoft Teams channel
* **Create Scratch Org:** Spin up a temporary Salesforce org from a source org
* **Generate Seed Data:** Export data from a Salesforce org as a reusable seed file
* **Load Seed Data:** Import a seed data file into a target Salesforce org
* **Insert into Supabase:** Insert a record into a Supabase table
* **Update Jira Ticket:** Update a Jira issue with a new status, a comment, or both

{% hint style="success" %}
Steps can be renamed once they are placed in an Automation.\
\
For example, "Send Teams Message" can be renamed to "Notify PMs".
{% endhint %}

### Template variables

Steps produce **output variables** that subsequent steps can reference using `{{StepName.field}}` syntax.\
\
Each step's expandable section below lists the outputs it produces.

The **Available Template Variables** helper in the step editor lists every variable currently available from earlier steps in the Automation.

Click any variable to insert it into a field.

## Create Salesforce Change

Creates a new Change record to track a set of metadata updates through your pipeline.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Create Salesforce Change step</strong></mark></summary>

**Parameters**

| Field                  | Required | Description                                          |
| ---------------------- | -------- | ---------------------------------------------------- |
| **Name**               | Yes      | Display name for this step in the Automation Builder |
| **Change Name**        | Yes      | Name of the Change record that will be created       |
| **Description**        | No       | Optional summary of what this Change contains        |
| **Salesforce Org**     | No       | Pre-select the org this Change is associated with    |
| **Metadata Selection** | No       | Metadata components to include in the Change         |

**Outputs**

This step produces the following template variables for use in subsequent steps:

* `{{StepName.change_id}}` - ID of the created Change record
* `{{StepName.change_name}}` - Name of the created Change record

**Usage notes**

* The Change ID output is the key input for the Commit Change and Deploy Package steps. Run Create Salesforce Change first when building a deployment flow.
* Salesforce Org and Metadata Selection can be left blank and configured in later steps.

</details>

## Commit Change

Retrieves metadata from a connected Salesforce org and commits it to a Git branch, packaging the change for deployment.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Commit Change step</strong></mark></summary>

**Parameters**

| Field                 | Required    | Description                                                                                     |
| --------------------- | ----------- | ----------------------------------------------------------------------------------------------- |
| **Name**              | Yes         | Display name for this step in the Automation Builder                                            |
| **Change ID**         | Yes         | The Change to commit. Use `{{StepName.change_id}}` to reference a Create Salesforce Change step |
| **Salesforce Org**    | Yes         | The org to retrieve metadata from                                                               |
| **Repository**        | Yes         | The Git repository to commit to                                                                 |
| **Branch**            | Conditional | The target branch. Required unless **Create new branch** is enabled                             |
| **Create new branch** | No          | When enabled, creates a new branch automatically instead of targeting an existing one           |

**Outputs**

* `{{StepName.job_id}}` - ID of the commit job
* `{{StepName.commit_hash}}` - Git commit hash of the committed metadata
* `{{StepName.branch}}` - Branch name where the commit was made

**Usage notes**

* Either the **Branch** or **Create new branch** must be set. The step will not save without one of them configured.
* The step polls for job completion and will fail if the job doesn't complete within 15 seconds. For large metadata payloads, ensure org connectivity is stable.

</details>

## Deploy Package

Deploys committed metadata to a target Salesforce org, running tests and validating quality gates before applying changes.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Deploy Package step</strong></mark></summary>

**Parameters**

| Field                     | Required | Description                                                                                   |
| ------------------------- | -------- | --------------------------------------------------------------------------------------------- |
| **Name**                  | Yes      | Display name for this step in the Automation Builder                                          |
| **Select Connection**     | Yes      | The pipeline connection that governs this deployment                                          |
| **Change ID**             | Yes      | The Change to deploy. Use `{{StepName.change_id}}` to reference an earlier step               |
| **Target Salesforce Org** | Yes      | The org to deploy the metadata to                                                             |
| **Test Level**            | No       | Which tests to run during deployment (see test levels below). Defaults to **Run Local Tests** |
| **Validation Only**       | No       | When enabled, validates the deployment without applying it. Useful for pre-checks             |

**Test levels**

| Option                  | Behavior                                                                          |
| ----------------------- | --------------------------------------------------------------------------------- |
| **No Test Run**         | Runs no tests. Use only for non-Apex metadata                                     |
| **Run Local Tests**     | Runs all tests defined locally in the target org (default)                        |
| **Run Specified Tests** | Runs only the tests specified in the deployment package                           |
| **Run All Tests**       | Runs every test in the target org. Slowest — blocks the pipeline during execution |

**Outputs**

* `{{StepName.deployment_id}}` - ID of the deployment record
* `{{StepName.job_id}}` - ID of the deployment job
* `{{StepName.status}}` - Deployment result: `completed` or `success`

**Usage notes**

* Deployments can take several minutes. The step polls for up to 10 minutes before timing out.
* If the deployment fails, the step surfaces up to five component and test failures with details.
* **Validation Only** is useful before a production deployment. Pair it with a manual approval step or Teams notification to review results before committing.

</details>

## Send Teams Message

Posts a message to a Microsoft Teams channel. Supports template variables so messages can include context from earlier steps.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Send Teams Message step</strong></mark></summary>

**Parameters**

| Field             | Required | Description                                                         |
| ----------------- | -------- | ------------------------------------------------------------------- |
| **Name**          | Yes      | Display name for this step in the Automation Builder                |
| **Teams Channel** | No       | The channel to post to. Defaults to **general** if left blank       |
| **Message**       | Yes      | The message content. Supports template variables from earlier steps |

**Outputs**

* `{{StepName.messageId}}` - ID of the sent message
* `{{StepName.timestamp}}` - When the message was sent (ISO 8601)
* `{{StepName.channel}}` - The channel the message was sent to

**Usage notes**

* Template variables make notifications context-aware. For example: `Deployment {{Deploy.status}} — commit {{CommitChange.commit_hash}} is live.`
* The Teams integration must be configured in **Integrations** before this step can be used.
* This step is non-blocking; it does not delay subsequent steps.

</details>

## Create Scratch Org

Creates a temporary Salesforce scratch org pre-loaded with metadata from a source org. Scratch orgs expire automatically after a configured number of days.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Create Scratch Org step</strong></mark></summary>

**Parameters**

| Field           | Required | Description                                                                                      |
| --------------- | -------- | ------------------------------------------------------------------------------------------------ |
| **Name**        | Yes      | Display name for this step in the Automation Builder                                             |
| **Dev Hub Org** | Yes      | The Dev Hub org used to create the scratch org                                                   |
| **Source Org**  | Yes      | The org whose metadata is pushed into the new scratch org                                        |
| **Duration**    | No       | How many days the scratch org should live (1–30). Defaults to **7**                              |
| **Alias**       | No       | A custom alias for the scratch org used in Salesforce CLI commands. Auto-generated if left blank |

**Outputs**

* `{{StepName.scratch_org_id}}` - ID of the created scratch org
* `{{StepName.username}}` - Login username for the scratch org
* `{{StepName.password}}` - Login password for the scratch org
* `{{StepName.instance_url}}` - API endpoint URL
* `{{StepName.login_url}}` - Browser login URL
* `{{StepName.access_token}}` - Bearer token for API access
* `{{StepName.alias}}` - Alias assigned to the org (use this in a Load Seed Data step)
* `{{StepName.expires_at}}` - Expiry timestamp (ISO 8601)

**Usage notes**

* Duration cannot be changed after the scratch org is created. Set the duration before running the Automation.
* The step typically takes 2–5 minutes, depending on the size of the source org's metadata.
* Use `{{StepName.alias}}` as the **Target Org Alias** input in a Load Seed Data step to immediately seed the new org.

</details>

## Generate Seed Data

Exports data from a Salesforce org as a structured seed file, ready to be loaded into another org via the Load Seed Data step.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Generate Seed Data step</strong></mark></summary>

**Parameters**

| Field                    | Required | Description                                                                           |
| ------------------------ | -------- | ------------------------------------------------------------------------------------- |
| **Name**                 | Yes      | Display name for this step in the Automation Builder                                  |
| **Source Org**           | Yes      | The org to export data from                                                           |
| **Export Configuration** | Yes      | A JSON object defining which objects and records to export (SFDMU format — see below) |

**Export configuration format**

The Export Configuration field accepts a JSON object that specifies which Salesforce objects to export and any filter conditions:

```json
{
  "objects": [
    {
      "name": "Account",
      "operation": "Retrieve"
    },
    {
      "name": "Contact",
      "operation": "Retrieve"
    },
    {
      "name": "Opportunity",
      "operation": "Retrieve",
      "where": "StageName = 'Won'"
    }
  ]
}
```

Use the `where` field to limit which records are exported — this is useful for excluding sensitive data or keeping seed files small.

**Outputs**

* `{{StepName.exportId}}` - ID of the export operation
* `{{StepName.exportPath}}` - Path to the exported data files (pass this to a Load Seed Data step)
* `{{StepName.exportedObjects}}` - An array of object types exported
* `{{StepName.recordCounts}}` - Record counts per object (e.g., `{Account: 500, Contact: 1200}`)

**Usage notes**

* This step is read-only. It does not modify the source org.
* Pass `{{StepName.exportPath}}` as the **Seed Data Path** in a Load Seed Data step.
* Large data exports can take several minutes and consume API quota. Use `where` filters to limit export size.
* The step has a 10-minute timeout.

</details>

## Load Seed Data

Imports seed data from a file into a target Salesforce org. Designed to follow a Generate Seed Data step or use a manually prepared seed file.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Load Seed Data step</strong></mark></summary>

**Parameters**

| Field                | Required | Description                                                                                                                        |
| -------------------- | -------- | ---------------------------------------------------------------------------------------------------------------------------------- |
| **Name**             | Yes      | Display name for this step in the Automation Builder                                                                               |
| **Target Org Alias** | Yes      | The alias or ID of the org to load data into. Use `{{CreateScratchOrg.alias}}` to target a scratch org created earlier in the flow |
| **Seed Data Path**   | Yes      | Path to the seed data directory. Use `{{GenerateSeedData.exportPath}}` to reference data generated earlier in the flow             |

**Outputs**

* `{{StepName.importId}}` - ID of the import operation
* `{{StepName.importedObjects}}` - An array of object types imported
* `{{StepName.recordCounts}}` - Record counts per object
* `{{StepName.importStatus}}` - Result: `completed`, `success`, or `partial`

**Usage notes**

* The most common pattern is to chain Generate Seed Data → Load Seed Data using template variables:
  * **Target Org Alias**: `{{CreateScratchOrg.alias}}`
  * **Seed Data Path**: `{{GenerateSeedData.exportPath}}`
* The target org must have the same object schema as the source org for the import to succeed.
* The step has a 10-minute timeout.

</details>

## Insert into Supabase

Inserts a record into a Supabase table. Useful for logging automation results, recording deployment history, or updating an external tracking system.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Insert into Supabase step</strong></mark></summary>

**Parameters**

| Field                   | Required | Description                                                                |
| ----------------------- | -------- | -------------------------------------------------------------------------- |
| **Name**                | Yes      | Display name for this step in the Automation Builder                       |
| **Supabase Connection** | Yes      | The Supabase integration to use. Configure connections in **Integrations** |
| **Table Name**          | Yes      | The name of the Supabase table to insert into                              |
| **Data**                | Yes      | A JSON object representing the row to insert. Supports template variables  |

**Data field format**

The **Data** field accepts a JSON object where keys map to column names in the target table:

```json
{
  "change_id": "{{CreateChange.change_id}}",
  "deployment_status": "{{Deploy.status}}",
  "commit_hash": "{{CommitChange.commit_hash}}",
  "timestamp": "{{trigger_data.timestamp}}"
}
```

**Outputs**

* `{{StepName.row_id}}` - ID of the inserted row
* `{{StepName.inserted_data}}` - Echo of the data that was inserted
* `{{StepName.insert_status}}` - Result: `completed`

**Usage notes**

* Column names in the Data object must match your Supabase table schema exactly.
* Template variables from earlier steps make this step useful as an audit log. Record the following in a single row:
  * Change ID
  * Deployment status
  * Commit hash
  * Timestamp
* The Supabase connection must be configured in **Integrations** before this step can be used.

</details>

## Update Jira Ticket

Updates a Jira issue with a new status, a comment, or both. Use this step to keep your Jira board in sync with what's happening in SRE.ai.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how to set up and customize the Update Jira Ticket step</strong></mark></summary>

**Parameters**

| Field               | Required | Description                                                                   |
| ------------------- | -------- | ----------------------------------------------------------------------------- |
| **Name**            | Yes      | Display name for this step in the Automation Builder                          |
| **Jira Connection** | Yes      | The Jira integration to use. Configure connections in **Integrations**        |
| **Issue Key**       | Yes      | The Jira issue to update (e.g., PROJ-123). Supports template variables        |
| **Status**          | No       | The status to transition the issue to (e.g., "In Review", "Done")             |
| **Comment**         | No       | A comment to add to the issue. Supports template variables from earlier steps |
| **Fields**          | No       | Additional Jira fields to update, as a JSON object                            |

**Outputs**

* `{{StepName.issueKey}}` - Key of the updated Jira issue
* `{{StepName.updatedFields}}` - List of fields that were updated

**Usage notes**

* At least one of **Status**, **Comment**, or **Fields** should be configured.&#x20;

{% hint style="danger" %}
The step has no effect if all three are empty.
{% endhint %}

* Template variables make comments context-aware. For example: `Deployment {{Deploy.status}} — commit {{CommitChange.commit_hash}} deployed successfully.`
* The status value must match a valid transition name in your Jira project. If the transition is not available for the issue's current state, the step will fail.
* The Jira integration must be configured in **Integrations** before this step can be used.

</details>


# Pipeline automation

Learn how SRE.ai can be used to facilitate pipeline automation

## Overview

Salesforce teams lose time to manual handoffs, waiting for a reviewer to approve, manually triggering a deployment, or tracking down which environment is out of sync.

**Pipeline automation** is about removing those handoffs by wiring together the events in your pipeline so the right things happen automatically.

SRE.ai addresses this through two features working in combination:

* **Pipelines** define the stages, branches, and quality gates that govern how changes move from development to production.
* **Automations** let you trigger multi-step workflows (deployments, branch merges, notifications) in response to events in your pipeline.

Together, they let you enforce standards automatically and reduce the manual coordination required to ship.

## Static code analysis

### Scenario

**Problem:**

A team wants to catch code quality issues, security vulnerabilities, and best practice violations before changes reach production.

Waiting until deployment to discover these problems creates rework and risk.

**SRE.ai's fit:**

SRE.ai incorporates static code analysis directly into the pull request review process so issues are caught and addressed early.

{% hint style="success" %}
Static code analysis ties into SRE.ai's quality gates and PR review workflows.&#x20;

Read [the Pipelines documentation](/setting-up-sre.ai/pipelines) for more on configuring quality gates at each stage.
{% endhint %}

### Who this is for

Teams that want to enforce code quality standards during their review process.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* At least one Pipeline configured with stages ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* A connected GitHub account ([see Integrations documentation](/setting-up-sre.ai/integrations))

#### Setup

Configure the Code Review quality gate on each stage where you want static analysis findings enforced.

1. Navigate to **Pipelines** and select your active pipeline.
2. Click on the stage where you want static analysis enforced (typically your **code integration** or **staging** stage) to open the Stage Details panel.
3. Under **Quality gates**, toggle **Enable Code Review** on.
4. Under **Block Review Comments**, select the minimum finding severity that should block a change from advancing:
   * **Critical**: only the most severe findings block promotion.
   * **High**: critical and high-severity findings block promotion.
   * **Medium**: critical, high, and medium severity findings block promotion.
   * See [the Pipelines documentation](/setting-up-sre.ai/pipelines) for the full list of quality gate options.
5. Repeat for any additional stages where you want analysis enforced. Teams typically set a higher severity threshold (less strict) in early stages and a lower threshold (more strict) as changes approach production.
6. Verify that your **GitHub integration** is active and that the repository is connected.
   * Navigate to **Integrations** and confirm GitHub shows a connected status.
   * [See the Integrations documentation](/setting-up-sre.ai/integrations) for setup steps if needed.

#### Example workflow

1. A developer commits changes, and SRE.ai detects the change in the connected repository.
2. SRE.ai scans the changed components for code quality issues, security vulnerabilities, and best practice violations.
3. Findings are surfaced in the change detail view, organized by severity. Developers can search for violations, review finding details, and dismiss findings with a recorded reason.
4. If the **Enable Code Review** gate is active for the target stage, the change's quality gate status reflects whether unresolved findings at or above the configured **Block Review Comments** severity are present.
5. Developers address flagged findings before advancing the change to the next stage.
6. Once no findings remain at or above the blocking severity, the change clears the gate and can advance.

#### Result

Code quality issues are identified and resolved before deployment rather than discovered after.

Changes that pass through this workflow meet the team's quality standards before they advance to staging or production, reducing rework and failed deployments.

</details>

## Back propagation

### Scenario

**Problem:**

A hotfix is deployed directly to production to resolve a critical issue.

Now the team needs those changes to flow back to lower environments so development and staging don't drift out of sync.&#x20;

Without back-propagation, teams risk building on outdated code or reintroducing the bug that the hotfix resolved.

**SRE.ai's fit:**

SRE.ai's Pipeline feature supports backpropagation workflows that automatically push changes from higher environments down to lower ones.

{% hint style="success" %}
Back propagation is closely tied to how pipeline stages and hotfix branches are configured.&#x20;

Read the [Pipelines documentation](/setting-up-sre.ai/pipelines) and [Release management strategies documentation](/best-practices/release-management-strategies) for more on stage hierarchies and hotfix workflows.
{% endhint %}

### Who this is for

Teams that deploy hotfixes directly to production need a reliable way to ensure those changes are reflected across all lower environments without manually cherry-picking commits or coordinating branch merges across the team.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* A Pipeline configured with a hotfix stage connected to production ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* At least two additional stages representing lower environments (e.g., staging, development)
* Automations configured to trigger on deployment events ([see Automations documentation](/using-sre.ai/automations))

#### Setup

Back propagation requires an Automation that triggers after a hotfix deployment and merges the changes into your lower-environment branches.

1. Navigate to the **Automations** page and click **New** to create a new Automation.
2. Name the Automation descriptively (e.g., "Back Propagate Hotfixes to Staging + Dev").
3. In the Automation Builder, click the **Trigger** block to open the Trigger panel.
4. Select **Deployment** as the Trigger type and configure the filters:
   * Under the **Org filter**, select your **production org**. This scopes the trigger to deployments targeting production only.
   * Under the **Status filter**, select **Success**. This ensures the automation fires only after a successful deployment, not on failures.
   * See [the Triggers customization documentation](/using-sre.ai/automations/triggers/triggers-customization) for details on each parameter.

{% hint style="info" %}
The Deployment trigger fires for all successful deployments to the selected org, not only hotfix deployments.&#x20;

If your team also deploys to production through the standard pipeline, the back-propagation automation will run for those deployments.&#x20;

This is typically safe, but worth confirming against your team's workflow.
{% endhint %}

5. Add a **Commit Change** Step to merge the hotfix changes into your **staging branch**. Configure it with the following parameters:
   * **Repository**: Select the repository connected to your pipeline
   * **Branch**: Select your staging branch
   * See [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for details on each parameter.
6. Add a second **Commit Change** Step to merge the hotfix changes into your **development branch**, configured the same way but targeting the development branch.
7. Optionally, add a **Send Teams Message** Step to notify your team that backpropagation has completed and to confirm which branches received the changes.
8. Click the **Activation** button to activate the Automation.

{% hint style="success" %}
Consider configuring this Automation alongside your hotfix stage setup, so it's ready the first time a hotfix is deployed.&#x20;

See [the Hotfix strategy use case](#hotfix-strategy) for the full walkthrough of the hotfix configuration.
{% endhint %}

#### Workflow

1. A hotfix is deployed directly to the production environment through the hotfix stage.
2. Once the hotfix is deployed to production, SRE.ai triggers an automation to initiate backpropagation.
3. The automation automatically merges the hotfix changes into the staging and development branches.
4. Each lower environment receives the changes, ensuring parity across the full pipeline without manual cherry-picking.
5. Back propagation is logged on the Changes page, providing a clear audit trail of what was propagated and when.

#### Result

All lower environments (staging, development, and any other configured stages) now include the hotfix changes.

The team can continue building on branches that reflect the current production state, eliminating drift and preventing the reintroduction of resolved issues.

</details>

## Hotfix strategy

### Scenario

**Problem:**

A critical bug has been discovered in production.

The team needs an expedited path to deploy a fix without going through the full development pipeline, while still maintaining governance, visibility, and an audit trail.

**SRE.ai's fit:**

SRE.ai's Pipeline feature includes a dedicated hotfix stage that branches off from staging and connects directly to production, providing a governed fast path for emergency fixes.

{% hint style="success" %}
The hotfix stage is available in the Release Flow pipeline template.&#x20;

Read [the Pipelines documentation](/setting-up-sre.ai/pipelines) for configuration details and [the Release management strategies documentation](/best-practices/release-management-strategies) for context on how hotfix stages fit into the broader release process.
{% endhint %}

### Who this is for

Teams that need to ship emergency fixes to production quickly while maintaining quality controls and traceability

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* A Pipeline configured using the Release Flow template, which includes a hotfix stage ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* At least one production environment mapped to the production stage
* Quality gates configured for the hotfix stage can be set differently from those in other stages to balance speed with safety.
* Optionally, an Automation configured to trigger back propagation after the hotfix deploys ([see the Back propagation use case](#back-propagation))

#### Setup

The hotfix stage is included in the Release Flow pipeline template, but you need to configure its environment mapping and quality gates before it's ready to use.

1. Navigate to **Pipelines** and select your Release Flow pipeline.
2. Click on the **Hotfix** stage to open the Stage Details panel.
3. Under **Environment mapping**, click **Add Environment**, then select the Salesforce org you want hotfixes deployed to. This is typically the same production org mapped to your production stage.
   * A green checkmark confirms the connection is validated.
4. Under **Quality gates**, configure the checks required for hotfix deployments. These can be set differently from your standard pipeline stages to balance speed with safety. Consider:
   * A lower test coverage threshold than your staging or production gates
   * Keeping static analysis requirements enabled to catch critical issues
   * Requiring at least one approval
   * See [the Pipelines documentation](/setting-up-sre.ai/pipelines) for more on quality gate configuration.
5. Optionally, configure a backpropagation automation to propagate hotfix changes to lower environments after deployment. This prevents drift between production and your development/staging branches.
   * Navigate to **Automations**, create a new Automation, and configure a **Deployment** trigger that listens for deployments to the hotfix stage.
   * Add Steps to merge the hotfix into your staging and development branches.
   * See [the Back propagation use case](#back-propagation) for a full walkthrough.

{% hint style="success" %}
Quality gates on the hotfix stage should reflect your team's minimum acceptable checks for emergency deployments. You can always tighten them later as your hotfix process matures.
{% endhint %}

#### Workflow

1. The team identifies a critical bug in production that requires an immediate fix.
2. A developer creates a hotfix branch that originates from the hotfix stage in the pipeline, branches off staging, and connects directly to production.
3. The developer implements the fix and commits to the hotfix branch.
4. The hotfix passes through the quality gates configured for the hotfix stage. These gates can be scoped differently from the standard pipeline stages to prioritize speed while still enforcing essential checks.
5. Once quality gates pass, the fix is deployed directly to production through the hotfix stage, bypassing the standard promotion path.
6. The deployment is tracked in the Changes page and Command Center, maintaining a full audit trail.
7. Optionally, a back propagation automation merges the hotfix changes into lower environments to maintain parity across the pipeline.

#### Result

The critical fix is live in production without the delay of a full pipeline promotion.

Quality gates ensured the fix met the team's minimum safety standards even on the expedited path.

The hotfix is fully tracked on the Changes page, and if backpropagation is configured, lower environments are automatically updated to reflect the fix, preventing drift and ensuring the bug isn't reintroduced in future deployments.

</details>


# Environment management

Learn how SRE.ai can be used to facilitate environment management

## Overview

Managing Salesforce environments is repetitive work.&#x20;

Sandbox refreshes need manual reconfiguration.&#x20;

Test data must be re-entered before every validation cycle. Moving records between environments requires careful coordination to avoid overwriting in-progress work.

**Environment management** is about keeping your environments in a consistent, usable state without relying on manual processes.

SRE.ai addresses this through **Automations**, which let you define and replay environment setup workflows (post-refresh configuration, test data seeding, selective record copying) triggered automatically by deployment events or on demand.&#x20;

For developer environments specifically, **Scratch Orgs** and **Sandbox Pools** let teams provision isolated, short-lived orgs per branch without contention.

## Sandbox refresh support

### Scenario

**Problem:**

A team periodically refreshes sandboxes from production to reset test environments.

After a refresh, specific configurations and data need to be reapplied.

Without automation, this process relies on a manual checklist that's easy to miss and slow to complete.

**SRE.ai's fit:**

SRE.ai's Automations let you define post-refresh steps (such as deploying configuration metadata or seeding test records) that execute automatically when a deployment to the refreshed org succeeds.

{% hint style="success" %}
This use case relies on SRE.ai's Automations feature.&#x20;

Read [the Automations documentation](/using-sre.ai/automations) for an overview of Triggers and Steps, and [the Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs) to confirm your sandbox is connected.
{% endhint %}

### Who this is for

Teams that run scheduled sandbox refreshes and need consistent post-refresh configuration across environments.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* A connected Salesforce org for the sandbox being refreshed ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))
* A committed metadata package containing your post-refresh configuration
* An Automation configured with a Deployment trigger ([see Automations documentation](/using-sre.ai/automations))

#### Setup

Create an Automation that fires when the refreshed sandbox receives a successful deployment, then re-applies your standard configuration.

1. Navigate to the **Automations** page and click **New** to open the Automation Builder.
2. Name the Automation descriptively (e.g., "Post-Refresh: QA Sandbox Configuration").
3. In the Automation Builder, click the **Trigger** block to open the Trigger panel.
4. Select **Deployment** as the Trigger type.
   * Under the **Org filter**, select the sandbox org to refresh.
   * Under the **Status filter**, select **Success**.
   * See [the Triggers customization documentation](/using-sre.ai/automations/triggers/triggers-customization) for details on each parameter.
5. Add a **Deploy Package** Step to redeploy your configuration metadata to the refreshed sandbox.
   * **Select Connection**: choose the pipeline connection for this sandbox
   * **Target Salesforce Org**: select the refreshed sandbox
   * **Test Level**: set according to your team's standards
   * See [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for details on each parameter.
6. Optionally, add a **Load Seed Data** Step to populate the sandbox with baseline test records after the metadata deployment completes.
   * **Target Org Alias**: the alias of the refreshed sandbox
   * **Seed Data Path**: path to a pre-generated seed file, or reference the output of a prior **Generate Seed Data** Step using `{{GenerateSeedData.exportPath}}`
7. Optionally, add a **Send Teams Message** Step to notify your team when the post-refresh setup is complete.
8. Click the **Activation** button to activate the Automation.

{% hint style="success" %}
If you also want to seed test data as part of this workflow, read the [Test data seeding use case](#test-data-seeding) below for a walkthrough of the Generate Seed Data and Load Seed Data steps.
{% endhint %}

#### Workflow

1. An admin initiates a sandbox refresh in Salesforce.
2. Once the refresh completes and SRE.ai detects a successful deployment to the refreshed org, the Automation triggers automatically.
3. The Deploy Package Step redeploys your configuration metadata to the sandbox.
4. If a Load Seed Data Step is configured, SRE.ai loads the baseline test records into the sandbox immediately after the deployment completes.
5. If a Send Teams Message Step is configured, SRE.ai posts a notification confirming that the sandbox is ready.

#### Result

The sandbox is restored to a working state, with all required configurations and test data automatically applied after the refresh.\
\
The team can begin testing immediately without working through a manual setup checklist.

</details>

## Test data seeding

### Scenario

**Problem:**

After a sandbox refresh or when spinning up a new environment, the team needs consistent test data to validate functionality.

Manually entering or scripting test records before each test run is time-consuming and error-prone.

**SRE.ai's fit:**

SRE.ai's Generate Seed Data and Load Seed Data Steps let you export a dataset from a reference org once and automatically replay it into any target environment.

{% hint style="success" %}
Test data seeding is handled through SRE.ai's Automations feature.&#x20;

Read [the Automations documentation](/using-sre.ai/automations) for an overview of how Triggers and Steps work together, and [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for the full parameter reference for each Step.
{% endhint %}

### Who this is for

Teams that need every environment to start with a known baseline of test data before validation begins.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* A Salesforce org containing the reference data you want to export as seed data ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))
* A target org (sandbox or scratch org) to load data into
* An Automation configured with a Manual or Deployment Trigger ([see Automations documentation](/using-sre.ai/automations))

#### Setup

Create an Automation that exports data from a reference org and loads it into the target environment.

1. Navigate to the **Automations** page and click **New** to open the Automation Builder.
2. Name the Automation descriptively (e.g., "Seed Test Data: QA Environment").
3. In the Automation Builder, click the **Trigger** block to open the Trigger panel.
4. Select **Manual** to trigger seeding on demand, or **Deployment** to trigger it automatically after a deployment completes.
5. Add a **Generate Seed Data** Step to export data from your reference org.
   * **Source Org**: the org containing your reference data
   * **Export Configuration**: a JSON object specifying which objects to export. For example:

```json
{
  "objects": [
    {
      "name": "Account",
      "operation": "Retrieve"
    },
    {
      "name": "Contact",
      "operation": "Retrieve"
    }
  ]
}
```

* Use the `where` field inside any object entry to filter which records are exported. See [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for the full export configuration reference.

6. Add a **Load Seed Data** Step to import the exported records into the target environment.
   * **Target Org Alias**: the alias of the target sandbox
   * **Seed Data Path**: `{{GenerateSeedData.exportPath}}`
7. Optionally, add a **Send Teams Message** Step to notify the team when seeding completes.
8. Click the **Activation** button to activate the Automation.

#### Example workflow

1. The team can activate the Automation manually from the Automations Builder, or it can trigger automatically after a deployment.
2. SRE.ai runs the Generate Seed Data Step, exporting the defined objects from the source org.
3. SRE.ai immediately runs the Load Seed Data Step, importing those records into the target environment.
4. The target org contains the full baseline of test records.
5. If a Send Teams Message Step is configured, SRE.ai posts a notification confirming that seeding is complete.

#### Result

The target environment contains a consistent baseline of test records.\
\
The team can begin validation immediately without manual data entry or custom scripts.

</details>

## Selective data copy between environments

### Scenario

**Problem:**

A team needs to move specific records (such as configuration data or reference tables) from one environment to another without running a full refresh.

A full refresh would overwrite other in-progress work in the target environment.

**SRE.ai's fit:**

The Generate Seed Data Step's Export Configuration lets you filter exactly which objects and records to export using SOQL queries.&#x20;

The Load Seed Data Step then imports only those records into the target org.

{% hint style="success" %}
This use case relies on SRE.ai's Generate Seed Data and Load Seed Data Steps.&#x20;

Read [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for the full Export Configuration reference and parameter details.
{% endhint %}

### Who this is for

Teams managing multiple active environments that need to share specific records without disrupting in-progress work.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* A source Salesforce org containing the records to copy ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))
* A target Salesforce org to receive the records
* An Automation configured with a Manual Trigger ([see Automations documentation](/using-sre.ai/automations))

#### Setup

Create an Automation that exports a specific subset of records from the source org and loads them into the target.

1. Navigate to the **Automations** page and click **New** to open the Automation Builder.
2. Name the Automation descriptively (e.g., "Selective Data Copy: Config Tables to QA").
3. In the Automation Builder, click the **Trigger** block to open the Trigger panel.
4. Select **Manual** as the Trigger type.
5. Add a **Generate Seed Data** Step to export only the records you need.
   * **Source Org**: the org containing the records to copy
   * **Export Configuration**: a JSON object specifying the objects and SOQL filters. For example, to copy only active price books and products:

```json
{
  "objects": [
    {
      "name": "Pricebook2",
      "operation": "Retrieve"
    },
    {
      "name": "Product2",
      "operation": "Retrieve",
      "where": "IsActive = true"
    }
  ]
}
```

* Use the `where` field to filter by any field on the object. Only records matching the condition are exported.

6. Add a **Load Seed Data** Step to insert the exported records into the target environment.
   * **Target Org Alias**: the alias of the target sandbox
   * **Seed Data Path**: `{{GenerateSeedData.exportPath}}`
7. Click the **Activation** button to activate the Automation.

{% hint style="success" %}
Keep the Export Configuration scoped to only the objects you need.&#x20;

Exporting unrelated objects increases runtime and API consumption on the source org.
{% endhint %}

#### Example workflow

1. The team manually activates the Automation in the Automations Builder.
2. SRE.ai runs the Generate Seed Data Step, exporting only the specified objects and records from the source org.
3. SRE.ai runs the Load Seed Data Step, inserting those records into the target org.
4. The target org receives the selected records without disrupting other in-progress work.

#### Result

The specified records are available in the target environment.\
\
No other in-progress work in the target org is affected, and no full sandbox refresh is required.

</details>

## Ephemeral environments

### Scenario

**Problem:**

A developer wants to spin up a temporary environment to test a feature branch in isolation, then tear it down when done.

Sharing a single sandbox across developers creates bottlenecks and contention.

**SRE.ai's fit:**

SRE.ai's Create Scratch Org Step provisions a temporary org pre-loaded with metadata from a source org, with an automatic expiration after a configured number of days.&#x20;

Teams can also configure a **Sandbox Pool** on the developer stage in Pipelines to maintain a pre-provisioned pool of orgs, with each org assigned per pull request.

{% hint style="success" %}
Ephemeral environments can be created via Automations or configured directly on a pipeline stage.&#x20;

Read [the Automations documentation](/using-sre.ai/automations) and [the Pipelines documentation](/setting-up-sre.ai/pipelines) for more on how both approaches work.
{% endhint %}

### Who this is for

Teams practicing parallel feature development who need isolated, short-lived environments per branch or developer.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

SRE.ai supports two approaches to ephemeral environments: creating scratch orgs on demand via an Automation, or configuring a Sandbox Pool on the developer pipeline stage so that each pull request is automatically assigned an available org.

#### What you'll need

* A connected Dev Hub org ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))
* A source org whose metadata will be loaded into the scratch org
* An Automation configured with a Manual or Deployment Trigger ([see Automations documentation](/using-sre.ai/automations)), for the on-demand approach
* At least one Pipeline configured with a developer stage, for the Sandbox Pool approach ([see Pipelines documentation](/setting-up-sre.ai/pipelines))

#### Setup

**Option A: Create scratch orgs on demand via Automation**

Use this approach when developers need a new isolated org at the start of a feature branch.

1. Navigate to the **Automations** page and click **New** to open the Automation Builder.
2. Name the Automation descriptively (e.g., "Spin Up: Feature Branch Environment").
3. In the Automation Builder, click the **Trigger** block to open the Trigger panel.
4. Select **Manual** as the Trigger type.
5. Add a **Create Scratch Org** Step.
   * **Dev Hub Org**: your connected Dev Hub
   * **Source Org**: the org containing the metadata baseline for the scratch org
   * **Duration**: the number of days the org should remain active before expiring automatically (1–30)
   * See [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for details on each parameter.
6. Optionally, add a **Load Seed Data** Step immediately after to seed test records into the new scratch org.
   * **Target Org Alias**: `{{CreateScratchOrg.alias}}`
   * **Seed Data Path**: path to a pre-generated seed file or a reference to a prior Generate Seed Data Step
7. Optionally, add a **Send Teams Message** Step to share the org URL and credentials with the developer.
   * Use `{{CreateScratchOrg.login_url}}` and `{{CreateScratchOrg.username}}` in the message body.
8. Click the **Activation** button to activate the Automation.

**Option B: Sandbox Pool on the developer pipeline stage**

Use this approach when every pull request should automatically receive a pre-provisioned org.

1. Navigate to **Pipelines** and select your active pipeline.
2. Click on the **Developer / Team / Project** stage to open the Stage Details panel.
3. Under **Salesforce org connections**, select **Sandbox Pool Orgs** as the org type.
   * See [the Pipelines documentation](/setting-up-sre.ai/pipelines) for more on Sandbox Pool Orgs and how they differ from regular org connections.
4. Configure the pool settings: pool size, active duration, and whether orgs auto-sync with the main branch.
5. Save the stage configuration. SRE.ai assigns an available org from the pool to each new pull request targeting this stage.

#### Example workflow

**On-demand via Automation:**

1. A developer activates the Automation from the Automations Builder when starting work on a feature branch.
2. SRE.ai provisions a scratch org and loads metadata from the source org into it.
3. If a Load Seed Data Step is configured, SRE.ai populates the org with test records immediately after provisioning.
4. If a Send Teams Message Step is configured, the developer receives the org URL and credentials.
5. The developer tests in the isolated environment for the duration of their feature work.
6. When the configured duration expires, Salesforce automatically decommissions the org.

**Via Sandbox Pool:**

1. A developer opens a pull request targeting the developer stage.
2. SRE.ai assigns an available org from the Sandbox Pool to the pull request.
3. The developer tests their changes in the assigned org without affecting any other developer's environment.
4. When the pull request is closed or merged, the org is returned to the pool or decommissioned based on the pool configuration.

#### Result

Each developer or feature branch has an isolated, temporary org for testing.\
\
Orgs expire or are decommissioned automatically, requiring no manual teardown.\
\
No developer's in-progress work is affected by another developer's changes.

</details>


# QA

Learn how SRE.ai can be used to facilitate QA

## Overview

Quality issues found after deployment are expensive.&#x20;

They require rework, rollback coordination, and often a second deployment cycle to resolve.

**QA** is about moving that discovery earlier, catching issues during the pipeline, before changes reach production.

SRE.ai addresses this by configuring quality gates at each pipeline stage.&#x20;

Gates enforce **Apex test execution** at a configurable test level, block changes that don't meet a minimum **code coverage threshold**, and surface **code analysis findings** with severity-based blocking rules.

A change can't advance to the next stage until it meets the standards you've defined for that stage.

## Apex test execution

### Scenario

**Problem:**

A team writes Apex tests to validate their Salesforce customizations, but has no way to ensure those tests run and pass before changes reach higher environments.

Without enforcement, test failures surface after deployment rather than before, creating rework and risk.

**SRE.ai's fit:**

SRE.ai runs Apex tests automatically as part of every deployment and enforces results through configurable quality gates on each pipeline stage.&#x20;

Teams choose which test level runs at each stage and set whether failures block promotion.

{% hint style="success" %}
Apex test execution is configured at the stage level in SRE.ai's Pipelines feature.&#x20;

Read [the Pipelines documentation](/setting-up-sre.ai/pipelines) for an overview of stages and quality gates.
{% endhint %}

### Who this is for

Teams with Apex test classes in their org who want test results to gate promotion between pipeline stages.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* At least one Pipeline configured with stages mapped to Salesforce environments ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* Apex test classes present in the target Salesforce org

#### Setup

Configure the Deploy Test Level quality gate on each stage where you want Apex tests enforced.

1. Navigate to **Pipelines** and select your active pipeline.
2. Click on the stage where you want test execution enforced to open the Stage Details panel.
3. Under **Quality gates**, locate the **Deploy Test Level** field and select the test scope for this stage:
   * **No Test Run**: skips all tests. Use only for stages targeting non-Apex metadata.
   * **Run Specified Tests**: runs only the test classes included in the deployed package.
   * **Run Local Tests**: runs all test classes defined locally in the target org. This is the recommended default for integration and staging stages.
   * **Run All Tests in Org**: runs every test class in the target org, including those from installed packages. Use this for pre-production gates that require full coverage.

{% hint style="warning" %}
**Run All Tests in Org can take 1–2 hours** and will block Salesforce's deployment queue for the target org.&#x20;

Avoid deploying other changes to that org until it completes.
{% endhint %}

4. Under **Quality gates**, locate the **Block Code Coverage Percentage** field and select the minimum coverage threshold required before changes can advance:
   * Available thresholds: **75%**, **80%**, **85%**, or **90%**.
   * Deployments that don't meet the threshold are blocked at this stage.
5. Repeat for any additional stages where you want test execution enforced. Teams typically apply stricter test levels and higher coverage thresholds as changes move closer to production.
6. Save the stage configuration.

{% hint style="success" %}
A common pattern is to **Run Local Tests** on the code integration stage and to **Run All Tests in Org** on the staging stage.&#x20;

This balances speed in early stages with thoroughness before production.
{% endhint %}

#### Example workflow

1. A developer promotes a change to the configured pipeline stage.
2. SRE.ai runs the Apex tests at the configured test level against the target environment.
3. Two progress indicators track execution in real time: **Deployment Progress** (components deployed) and **Test Execution Progress** (tests passed vs. failed).
4. When execution completes, test results are surfaced in the deployment view:
   * **Test Failures**: failed test methods with failure messages and stack traces.
   * **Test Successes**: passing test methods.
   * **Code Coverage**: per-class coverage percentages against the configured threshold.
5. If all tests pass and coverage meets the threshold, the change advances through the quality gate. If any test fails or coverage falls short, the change is blocked at this stage until the issues are resolved.

#### Result

Every deployment through the configured stage is validated by Apex tests before advancing.\
\
Test failures and coverage gaps are surfaced with class-level detail and stack traces, giving developers the information they need to fix issues before they reach production.

</details>

## Regression suite execution

### Scenario

**Problem:**

Before any production deployment, a team needs to confirm that no existing functionality has broken.

Limiting the test run to only the changed components risks missing regressions in untouched code that depends on the deployed changes.

**SRE.ai's fit:**

Configuring the **Run All Tests in Org** test level on the staging stage ensures that every Apex test class in the org executes before changes can advance to production, providing a full regression sweep as a mandatory gate.

{% hint style="success" %}
Full regression execution relies on the Deploy Test Level quality gate in SRE.ai's Pipelines feature.&#x20;

Read [the Pipelines documentation](/setting-up-sre.ai/pipelines) for more on quality gate configuration and stage setup.
{% endhint %}

### Who this is for

Teams that require a full Apex test sweep as a mandatory checkpoint before promoting changes to production.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

#### What you'll need

* A Pipeline configured with a staging or pre-production stage that precedes the production stage ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* Apex test classes are present in the staging org

#### Setup

Configure the staging stage to run every test class in the org before changes can advance.

1. Navigate to **Pipelines** and select your active pipeline.
2. Click on your **staging** (or pre-production) stage to open the Stage Details panel.
3. Under **Quality gates**, set the **Deploy Test Level** to **Run All Tests in Org**.
   * This runs every test class in the target org (not just the tests in the deployed package), ensuring full coverage of all existing functionality.
4. Under **Quality gates**, set the **Block Code Coverage Percentage** to your team's required threshold (75%, 80%, 85%, or 90%).
   * Changes that don't meet the threshold are blocked at this stage, even if all tests pass.
5. Save the stage configuration.

{% hint style="warning" %}
**Run All Tests in Org can take 1–2 hours** and blocks Salesforce's deployment queue for the staging org during execution.&#x20;

Schedule production deployments to account for this window, and avoid deploying other changes to the staging org while a regression run is in progress.
{% endhint %}

#### Example workflow

1. A developer promotes a change to the staging stage.
2. SRE.ai triggers a full test run against the staging org. Every Apex test class executes, not just the tests in the deployed package.
3. The deployment view tracks execution in real time, showing test successes and failures as they complete.
4. When execution finishes, the deployment view displays:
   * **Test Failures**: any test methods that failed, with failure messages and stack traces.
   * **Code Coverage**: per-class coverage percentages against the configured threshold, including a list of classes that fall below the requirement.
5. If all tests pass and every class meets the coverage threshold, the change is cleared to advance to production. If any test fails or coverage falls short, the change is blocked at the staging stage until the issues are resolved.

#### Result

Production deployments only proceed after every test class in the staging org passes and coverage requirements are met.\
\
Teams catch regressions in dependent code (not just the changed components) before any change reaches production.

</details>


# Ticket to deploy

Learn how SRE.ai's agent chain delivers a Salesforce work item from ticket to deployed change

## Overview

A **Change** is SRE.ai's core unit of work — the thing being delivered. A Change can represent a bug, a defect, a task, or a user story. It is the Salesforce work item moving through your pipeline from intake to production.

Delivering a Change involves more than writing code. It moves through design, implementation, code review, testing, deployment, and documentation — across multiple people, tools, and handoffs. Each step takes time. Each handoff creates waiting. When issues surface late in review, or documentation gets skipped, the total time to complete the work grows further.

**The problem ticket to deploy solves is time** — the accumulated time spent across every stage of delivery, and the inconsistent quality that results when that process depends too heavily on a few experienced people.

**The solution is delegation.** When a Change is created and a Jira ticket linked, SRE.ai activates a chain of agents that takes over the delivery work: spec, design, build, code review, test, fix, and deploy. Humans confirm at critical gates. The agents carry the rest.

SRE.ai enables this through four capabilities working together:

* **Agents** handle the delivery chain — design, implementation, code review, and deployment — with human confirmation at each stage.
* **Changes** track the full lifecycle — commits, pull requests, quality findings, test results, and deployments — in a single audit trail.
* **Jira integration** links a ticket to a Change so the agent chain has context when it starts and can close the ticket when the work ships.
* **Automations** close the loop by updating the originating Jira ticket automatically after a successful deployment.

## Agent-driven delivery from ticket to deployed change

### Scenario

**Problem:**

Delivering a Salesforce Change — whether it's a bug, a defect, a task, or a user story — involves a long sequence of steps that pass through multiple hands.

A ticket arrives. Someone designs the solution. A developer builds it. A reviewer checks the code. Issues get found and fixed. The change gets deployed. Documentation gets written. The Jira ticket gets updated. Each stage requires a handoff. Each handoff creates waiting time. When review cycles uncover problems, the sequence restarts and the total time grows.

The sum of that time — across every handoff, every wait, every rework cycle — is what makes Salesforce delivery slow and expensive.

**SRE.ai's fit:**

When a Change is created and assigned in SRE.ai, a chain of agents takes over the delivery work. The Design Agent produces a technical spec. After human approval, the Build Agent implements it, following the repo's existing patterns and committing to a feature branch. The Code Review Agent surfaces issues. If fixes are needed, agents address them. The Deploy Agent ships the change to the target environment.

Humans confirm at the gates that matter — approving the design, reviewing generated code, authorizing deployment — without carrying the work between those gates themselves.

{% hint style="success" %}
This use case relies on SRE.ai's Agents, Changes, and Jira integration features. Read [the Agents documentation](/using-sre.ai/agents) for an overview of the Design, Build, and Deploy Agents, [the Changes documentation](/using-sre.ai/changes) for how work is tracked, and [the Integrations documentation](/setting-up-sre.ai/integrations) for Jira connection setup.
{% endhint %}

### Who this is for

Teams delivering Salesforce Changes who want to reduce the total time from ticket to deployed change — without sacrificing consistency, quality, or traceability.

{% hint style="info" %}
Particularly useful for delivery teams where senior engineers are pulled into every stage of the process to compensate for inconsistent practices. The agent chain produces consistent, reviewable outputs at each stage, so senior review is focused on approvals rather than corrections.
{% endhint %}

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* A connected GitHub repository ([see Integrations documentation](/setting-up-sre.ai/integrations))
* At least one connected Salesforce org ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))
* A connected Jira integration, if linking tickets ([see Integrations documentation](/setting-up-sre.ai/integrations))

**Workflow**

Agents are activated in natural language from the Command Center. No special commands are required.

**1. Create the Change and link the ticket**

1. Open the **Command Center** and describe the work to be done — the bug, defect, task, or user story.
2. SRE.ai creates a **Change** to track the full delivery lifecycle.
3. In the Change detail view, navigate to the **External Issues** section and link the Jira ticket.
   * SRE.ai syncs the ticket's key, summary, and status and displays them alongside the Change.
   * The agent chain will use this context when designing and building the solution.

**2. Design phase**

1. SRE.ai activates the **Design Agent**. The agent explores the repository structure, examines relevant metadata in the connected org, and researches best practices for the change type.
2. The Design Agent produces a design document containing:
   * Success criteria
   * Architecture decisions
   * Implementation plan
   * Testing strategy
   * Risk notes
3. The design document is created with a status of **Draft**. A team member reviews it and sets the status to **Approved** when the approach is confirmed.
   * Designs can also be set to **Under Review**, **Implemented**, or **Archived** to reflect their current state.
4. No implementation begins until the design is approved.

**3. Build phase**

1. With an approved design, the **Build Agent** activates from the Command Center.
2. The Build Agent:
   * Creates a feature branch from main
   * Generates the required code and metadata files, following the repo's existing patterns and naming conventions
   * Validates the changes against the connected org
   * Commits the result to the feature branch
3. The agent's task is tracked on the linked Change, providing visibility into what was created, which files were modified, and the commit it produced.

**4. Code review and fix phase**

1. SRE.ai runs code analysis on the committed files and surfaces findings in the Change view — covering code quality, security vulnerabilities, performance, and test coverage.
2. Findings are posted as inline comments on the pull request so reviewers see them without leaving the code review.
3. If issues need to be addressed, the **Build Agent** can be invoked to fix identified findings before the change advances.
4. Once findings at or above the blocking severity are resolved, the Change clears the quality gate and can be promoted.

**5. Deploy phase**

1. The **Deploy Agent** handles deployment to the target environment.
2. Before executing, the agent confirms the target and surfaces what will change.
3. The deployment is logged on the Change timeline with a timestamp and result.
4. If an Automation is configured to update the linked Jira ticket on successful deployment, it fires automatically at this point — see the [Automated Jira updates on deployment](#automated-jira-updates-on-deployment) scenario below.

**Result**

The Change moves from ticket to deployed code through an agent-driven chain, with humans confirming the design, the implementation, and the deployment.

Total delivery time falls because agents carry the work between human gates rather than the work sitting idle waiting for the next person to pick it up. Delivery quality improves because every stage — design, build, review, test — produces a consistent, documented output regardless of who initiated the work.

</details>

## Automated Jira updates on deployment

### Scenario

**Problem:**

When a Change deploys, someone has to manually update the corresponding Jira ticket — moving it to Done, adding a comment, or recording which environment received it.

This is a routine step, but when it is skipped, the Jira backlog drifts out of sync with what has actually shipped.

**SRE.ai's fit:**

SRE.ai's Automations include an **Update Jira Ticket** step that fires after a successful deployment and updates the linked Jira issue automatically — no manual action required.

{% hint style="success" %}
This use case relies on SRE.ai's Automations feature and the Jira integration. Read [the Automations documentation](/using-sre.ai/automations) for an overview of Triggers and Steps, [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for the Update Jira Ticket parameter reference, and [the Integrations documentation](/setting-up-sre.ai/integrations) for Jira connection setup.
{% endhint %}

### Who this is for

Teams that track Salesforce delivery in Jira and want ticket status to stay accurate without relying on developers to update tickets after deployment.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* A connected Jira integration ([see Integrations documentation](/setting-up-sre.ai/integrations))
* A Pipeline configured with at least one stage mapped to a Salesforce environment ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* Changes with linked Jira issues ([see Changes documentation](/using-sre.ai/changes))

**Setup**

Create an Automation that fires when a deployment to a target environment succeeds and updates the linked Jira ticket.

1. Navigate to the **Automations** page and click **New** to open the Automation Builder.
2. Name the Automation descriptively (e.g., "Update Jira on Production Deployment").
3. In the Automation Builder, click the **Trigger** block to open the Trigger panel.
4. Select **Deployment** as the Trigger type and configure the filters:
   * Under **Org filter**, select the production org you want to trigger on.
   * Under **Status filter**, select **Success**.
   * See [the Triggers customization documentation](/using-sre.ai/automations/triggers/triggers-customization) for details on each parameter.
5. Add an **Update Jira Ticket** Step and configure which fields to update on the linked issue — for example, setting the status to Done and adding a deployment comment.
   * See [the Steps customization documentation](/using-sre.ai/automations/steps/steps-customization) for the full parameter reference.
6. Click the **Activation** button to activate the Automation.

**Example workflow**

1. A Change linked to a Jira issue is promoted through the pipeline and deployed to production.
2. SRE.ai detects the successful deployment and triggers the Automation.
3. The **Update Jira Ticket** Step fires, updating the linked issue's status and adding a deployment note.
4. The Jira ticket reflects the shipped state without any manual action from the developer.

**Result**

Jira tickets are updated automatically when a deployment succeeds.

The backlog reflects what has shipped without depending on developers to update tickets after the fact.

</details>


# Code review and remediation

Learn how SRE.ai surfaces code and metadata quality issues and supports fixing them before they become technical debt

## Overview

Poor code quality is rarely a single event.

Issues accumulate because review is inconsistent, declarative metadata gets skipped, and senior engineers become bottlenecks — pulled into fix cycles that could have been caught earlier.

**Code review and remediation** is about making that process automatic, consistent, and resolution-oriented.

SRE.ai addresses this through two layers:

* **Automated analysis** runs on every change — static analysis using PMD and ESLint rules, AI-generated observations about patterns and risks, and dependency reference checks. Findings are surfaced with severity levels in the change detail view and posted as inline comments on pull requests.
* **Agent-assisted remediation** lets teams fix flagged issues without a separate rework cycle. Once findings are surfaced, the Build Agent can resolve them directly.

## Automated code and metadata review

### Scenario

**Problem:**

Code review depends on the availability of senior engineers.

When they're unavailable or overloaded, review gets deferred, rushed, or skipped entirely. Declarative work — validation rules, flows, field configurations — rarely goes through the same review process as developer code at all.

Issues that should have been caught during development accumulate as technical debt or escape into production.

**SRE.ai's fit:**

SRE.ai runs automated code analysis on every change as soon as it's tracked — no manual trigger required. Each change receives a complete set of findings: static analysis violations, AI-generated observations, and dependency checks, organized by severity.

{% hint style="success" %}
Automated code analysis is part of SRE.ai's Changes feature. Read [the Changes documentation](/using-sre.ai/changes) for an overview of how findings are surfaced, and [the Pipelines documentation](/setting-up-sre.ai/pipelines) for how quality gates use findings to control promotion.
{% endhint %}

### Who this is for

Teams that want every Salesforce change reviewed automatically, including declarative metadata that would otherwise bypass human review.

{% hint style="info" %}
Particularly useful for teams where Salesforce admins commit configuration changes — field modifications, validation rules, flows — that don't go through the same review process as developer code.
{% endhint %}

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* A connected GitHub repository with changes being tracked ([see Integrations documentation](/setting-up-sre.ai/integrations))
* At least one Change in SRE.ai ([see Changes documentation](/using-sre.ai/changes))

**How it works**

No additional setup is required for automated analysis to run. Once a repository is connected and changes are tracked, SRE.ai runs the following on every change:

* **Static code analysis** — PMD and ESLint rule violations surfaced with rule name, file location, and severity.
* **AI analysis** — pattern-based observations about code quality, security risks, performance concerns, and governor limit exposure, generated by SRE.ai's AI layer and distinct from static rule violations.
* **Dependency reference checks** — components in the change are checked for missing or broken references.

Findings appear in the **Code Quality** section of the change detail view, organized by severity: **Critical**, **High**, **Medium**, **Low**, and **Info**.

Each finding can be:

* **Reviewed** — expand the finding detail, file location, and line reference.
* **Dismissed** — mark as dismissed with a recorded reason, visible in the audit trail.
* **Resolved** — set to Resolved once the issue has been addressed.

When a pull request is open for the change, SRE.ai posts findings as inline code review comments on the PR, making them visible to reviewers without requiring them to open SRE.ai separately.

**Example workflow**

1. A developer commits changes to a feature branch connected to a SRE.ai pipeline.
2. SRE.ai detects the commit and begins analysis — static rules, AI observations, and dependency checks run automatically.
3. Findings are surfaced in the change detail view. The developer reviews them, addresses issues, and dismisses intentional patterns with a recorded reason.
4. Pull request reviewers see the same findings as inline comments without leaving the PR.
5. Once findings are resolved or acknowledged, the change is ready to advance through the pipeline's quality gates.

**Result**

Every change receives a consistent, automated review regardless of whether a senior engineer is available.

Findings are surfaced at the point of development, not after deployment, and are tracked with resolution status and dismissal reasons for a complete audit trail.

</details>

## Blocking changes on unresolved findings

### Scenario

**Problem:**

Analysis findings are surfaced but not enforced.

Without a blocking mechanism, developers can acknowledge findings and promote changes anyway. Issues still reach production.

**SRE.ai's fit:**

SRE.ai's pipeline quality gates enforce code review findings at each stage. Configure a severity threshold and any change carrying unresolved findings at or above that severity is blocked from advancing until the issues are resolved or dismissed.

{% hint style="success" %}
Severity-based blocking is configured through SRE.ai's Pipelines feature. Read [the Pipelines documentation](/setting-up-sre.ai/pipelines) for the full quality gate configuration reference, and [the Pipeline automation use case](/use-cases/pipeline-automation#static-code-analysis) for a setup walkthrough.
{% endhint %}

### Who this is for

Teams that want code quality standards enforced structurally, not left to individual discipline.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* A Pipeline configured with at least one stage ([see Pipelines documentation](/setting-up-sre.ai/pipelines))
* A GitHub integration active and connected to a repository ([see Integrations documentation](/setting-up-sre.ai/integrations))

**Setup**

Configure the Code Review quality gate on each stage where you want findings enforced.

1. Navigate to **Pipelines** and select your active pipeline.
2. Click on the stage where you want blocking enforced to open the Stage Details panel.
3. Under **Quality gates**, toggle **Enable Code Review** on.
4. Under **Block Review Comments**, select the minimum severity that should block promotion:
   * **Critical**: only the most severe findings block promotion.
   * **High**: critical and high-severity findings block promotion.
   * **Medium**: critical, high, and medium severity findings block promotion.
5. Repeat for additional stages. A common pattern is a less strict threshold on early stages (High or Critical) and a stricter threshold (Medium) on staging and pre-production stages.
6. Save the stage configuration.

**Example workflow**

1. A developer promotes a change to the configured stage.
2. SRE.ai evaluates the change's code quality findings against the configured blocking threshold.
3. If any unresolved findings meet or exceed the configured severity, the quality gate blocks the change from advancing.
4. The developer resolves or dismisses the flagged findings.
5. Once no blocking findings remain, the quality gate clears and the change can advance.

**Result**

Changes can't advance past the configured stage while unresolved findings at the blocking severity are present.

Quality standards are enforced at the gate, not left to code review discipline.

</details>

## Agent-assisted remediation

### Scenario

**Problem:**

Findings are surfaced and blocked at the gate, but fixing them still requires a developer to context-switch into a manual review-and-fix cycle.

For teams where code review is already a bottleneck, adding a mandatory remediation step slows delivery further — unless there's a faster way to resolve findings.

**SRE.ai's fit:**

Once findings are surfaced in a Change, the Build Agent can address them directly. A team member points the agent at the findings to resolve, and the agent implements fixes, validates them against the connected org, and commits the changes to the feature branch.

{% hint style="success" %}
Agent-assisted remediation uses SRE.ai's Build Agent. Read [the Agents documentation](/using-sre.ai/agents) for an overview of how the Build Agent works and how agent tasks are tracked in Changes.
{% endhint %}

### Who this is for

Teams where code review findings are surfaced but remediation creates a secondary bottleneck — pulling senior engineers into fix cycles after initial review.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* A connected GitHub repository ([see Integrations documentation](/setting-up-sre.ai/integrations))
* A connected Salesforce org ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))
* A Change with active code quality findings ([see Changes documentation](/using-sre.ai/changes))

**Workflow**

1. Open the **Command Center** and describe the findings you want to resolve. For example: *"Fix the critical and high findings on the OpportunityTrigger change — the governor limit exposure and the missing null checks."*
2. SRE.ai activates the **Build Agent**. The agent reviews the flagged findings, implements fixes on the connected feature branch, validates the changes against the org, and commits the result.
3. The agent's task is tracked on the Change — which findings were addressed, what files were modified, and the resulting commit.
4. The developer reviews the agent's output before advancing the change.
5. Once the findings are resolved, the quality gate clears and the change can be promoted to the next stage.

**Result**

Flagged findings are resolved without a separate manual fix cycle.

Senior engineers review the agent's output rather than implementing each fix themselves, reducing the time between "finding surfaced" and "change ready to advance."

</details>


# AI delivery standard

Learn how SRE.ai supports a governed, repeatable approach to AI-assisted Salesforce delivery

## Overview

AI adoption in Salesforce delivery teams is often uneven.

Some individuals use AI tools independently, others don't. Outputs vary. There's no shared way to confirm that AI-generated work is correct before it ships, no audit trail of what the AI produced versus what a human approved, and no consistent set of guardrails across the team.

**AI delivery standard** is about making AI usage in delivery consistent and governable — so the whole team benefits from AI without losing control over what ships.

SRE.ai provides a structured delivery flow where:

* AI work begins with a **design phase** that a human reviews and approves before implementation starts.
* Agents surface their plans and intermediate artefacts at each step, so a team member can confirm the approach before the agent proceeds.
* Every agent task is linked to a **Change**, creating a full audit trail of what was designed, built, reviewed, and deployed — and by whom.
* **Roles and permissions** control who can trigger agents, approve designs, and promote changes through the pipeline.

## Structured design-before-build flow

### Scenario

**Problem:**

AI-generated implementations vary in quality. Without a mandatory design step, AI builds solutions that may be functional but not aligned with the org's architecture, existing patterns, or team standards.

When that happens, the team still needs a senior engineer to review and often rewrite the output — which eliminates the efficiency gain and creates inconsistency across the codebase.

**SRE.ai's fit:**

SRE.ai enforces a design-before-build sequence through the Design Agent and Build Agent. The Design Agent produces a structured plan that must be reviewed and approved by a team member before the Build Agent begins implementation. No code is written until a human has confirmed the approach.

{% hint style="success" %}
This flow relies on SRE.ai's Agents feature. Read [the Agents documentation](/using-sre.ai/agents) for how the Design Agent, Build Agent, and Deploy Agent work and how their tasks are linked to Changes.
{% endhint %}

### Who this is for

Teams that want to use AI in delivery but need consistent, reviewable output — not ad hoc generations that vary by individual.

{% hint style="info" %}
Particularly useful for teams working across multiple orgs or projects where delivery standards need to hold regardless of who is doing the implementation work.
{% endhint %}

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* A connected GitHub repository ([see Integrations documentation](/setting-up-sre.ai/integrations))
* At least one connected Salesforce org ([see Salesforce Orgs documentation](/setting-up-sre.ai/salesforce-orgs))

**Workflow**

SRE.ai's Agents are activated in natural language from the Command Center. No special commands are required.

**Step 1 — Design:**

1. Open the **Command Center** and describe the change to implement.
2. The **Design Agent** activates. It explores the repository structure, examines relevant metadata in the org, and produces a design document containing:
   * Success criteria
   * Architecture and approach decisions
   * Implementation plan
   * Testing strategy
   * Risk notes
3. The design is created with a status of **Draft**.
4. A team member reviews the design and sets the status to **Approved** when the approach is confirmed.
   * If the approach needs adjustment, the design can be revised before approval.
   * Implementation does not begin until the design status is Approved.

**Step 2 — Build:**

1. With an approved design, activate the **Build Agent** from the Command Center.
2. The agent creates a feature branch, generates the required code and metadata following the repo's existing patterns, validates the result against the connected org, and commits the changes.
3. The agent surfaces its progress and artefacts as the task runs — branch created, files modified, validation result, commit reference.
4. The developer reviews the agent's output and the linked Change before promoting the work.

**Step 3 — Deploy:**

1. The **Deploy Agent** is activated from the Command Center to handle deployment.
2. The agent identifies the components to deploy, confirms the target environment, executes the deployment with validations, and reports the result.
3. All deployment activity is recorded on the linked Change.

**Result**

AI-generated work follows a consistent sequence: design → human approval → build → human review → deploy.

The team benefits from AI-assisted delivery without losing the review and approval steps that ensure quality and alignment with org standards.

</details>

## Traceability and audit trail for AI-assisted work

### Scenario

**Problem:**

When AI tools are used without a structured workflow, it's difficult to answer basic questions: who triggered this change, what did the AI generate, and did a human review it before it shipped?

Without that visibility, teams can't audit AI-assisted work or verify that their own delivery standards were followed.

**SRE.ai's fit:**

Every agent task in SRE.ai is linked to a Change, which records the full lifecycle — what the agent produced, which files were modified, commits, pull requests, quality findings, test results, and deployments — with timestamps and actor attribution throughout.

{% hint style="success" %}
Traceability for AI-assisted work is provided through SRE.ai's Changes feature. Read [the Changes documentation](/using-sre.ai/changes) for an overview of what is tracked across the change lifecycle.
{% endhint %}

### Who this is for

Teams that need to demonstrate that AI-assisted Salesforce changes followed a governed review and approval process before shipping.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What is recorded on every Change**

SRE.ai's Changes feature records the following for every change that moves through the platform, including changes produced by agents:

* **Commits** — every commit associated with the change, including those produced by the Build Agent.
* **Pull requests** — PR status, reviewer activity, and merge outcome.
* **Code quality findings** — static analysis violations, AI observations, and dependency checks, with resolution status and dismissal reasons.
* **Test coverage** — per-class Apex test coverage against configured thresholds.
* **Deployments** — deployment status, timestamp, target environment, and deployer.
* **Activity timeline** — a chronological log of all significant lifecycle events with timestamps and actor attribution.
* **Design artefacts** — design documents produced by the Design Agent, with their review status (Draft, Under Review, Approved, Implemented, Archived).
* **External issue links** — linked Jira or Linear issues, synced throughout the lifecycle.

**Example workflow**

1. A team member activates the Design Agent to plan a Salesforce change.
2. The design is created as a Draft and linked to a Change. The reviewer sets the status to Approved — this action is logged on the Change timeline.
3. The Build Agent implements the approved design. Its commits and file modifications are recorded on the Change.
4. Automated code analysis runs on the committed work. Findings are surfaced, and resolutions or dismissals are recorded with reasons.
5. The change is deployed to production through the pipeline. The deployment event is logged with timestamp and deployer identity.
6. The full trail — design, build, review, and deployment — is available on the Change detail view at any time.

**Result**

Every AI-assisted change has a complete, auditable record: what was designed, who approved it, what was built, what was found during review, and when and by whom it was deployed.

Teams can answer audit questions about any change without reconstructing the history from separate systems.

</details>

## Access controls for AI-assisted delivery

### Scenario

**Problem:**

Not everyone on a team should have the same level of access to trigger agents, approve designs, or promote changes through the pipeline.

Without access controls, a developer could trigger a build without a reviewed design, or promote a change without the appropriate approval — bypassing the governance steps that make AI-assisted delivery safe.

**SRE.ai's fit:**

SRE.ai's role-based permissions model controls what each team member can do across Pipelines, Changes, and other platform features. Assigning roles based on responsibility ensures that governance steps — approving a design, configuring pipeline standards, promoting to production — are performed by the right people.

{% hint style="success" %}
Access controls are configured through SRE.ai's Roles and permissions feature. Read [the Roles and permissions documentation](/setting-up-sre.ai/roles-and-permissions) for the full permissions reference by role and area.
{% endhint %}

### Who this is for

Teams that need AI-assisted delivery workflows to follow defined approval paths, with the right people responsible for each step.

<details>

<summary><mark style="background-color:yellow;"><strong>Click to learn how SRE.ai addresses this scenario</strong></mark></summary>

**What you'll need**

* Team members invited to the SRE.ai workspace
* Roles assigned based on each member's responsibilities ([see Roles and permissions documentation](/setting-up-sre.ai/roles-and-permissions))

**Role overview**

SRE.ai provides three roles:

* **Owner** — full access to all platform features, including pipeline management, stage configuration, and team administration.
* **Admin** — all permissions except deleting pipelines. Suitable for delivery leads and senior engineers who configure standards but should not be able to delete production pipeline configurations.
* **Member** — read-only access to pipelines and team settings. Suitable for contributors who execute delivery work within the configured standards.

See [the Roles and permissions documentation](/setting-up-sre.ai/roles-and-permissions) for the full permissions breakdown by area.

**Setup**

Assign roles to reflect your team's delivery structure.

1. Navigate to **Team settings** and open the **Members** list.
2. Assign roles based on responsibility:
   * **Owners or Admins**: delivery leads, senior engineers, platform owners — those responsible for configuring pipeline standards and approving design artefacts.
   * **Members**: developers and admins executing delivery work within the configured standards.
3. Review role assignments as the team grows or responsibilities shift.

**Result**

Platform capabilities are accessible based on role, ensuring that governance steps — pipeline configuration, design approval, production promotions — are performed by the appropriate team members.

AI-assisted delivery follows defined paths without relying on individual discipline to enforce them.

</details>


# Salesforce troubleshooting

## Salesforce connection issues

#### Instance connection vs. login

**Important clarification:** Connecting a Salesforce instance is separate from logging into SRE.ai with Salesforce.

* **Salesforce Login:** Uses your Salesforce credentials to authenticate you into the SRE.ai application (like "Sign in with Google")
* **Instance Connection:** Links your Salesforce org (production or sandbox) to SRE.ai so the platform can perform deployments and other operations

You can log into SRE.ai with Google or Microsoft Teams and still connect your Salesforce instances for deployments. The login method doesn't affect which Salesforce orgs you can connect.

#### Who needs to connect instances?

**Question:** When a new developer joins, do they need to connect their own sandbox?

**Answer:** No. Once an admin connects a Salesforce instance (production or sandbox), all team members can use that connection. Only one person needs to establish the connection. After that, everyone on the team can work with that environment.

The connection uses JWT authentication behind the scenes, so individual users authenticate with their own Salesforce credentials when performing actions, but the instance connection itself persists for the whole team.

#### Connection persists after user deactivation

**Question:** If the admin who connected an instance is deactivated in Salesforce, will the connection break?

**Answer:** No. The instance connection remains established even if the original connecting user is deactivated. Individual users will authenticate with their own credentials when performing operations in that environment.

#### Security warning when connecting Salesforce instance

**Symptom:** When connecting a Salesforce org (production or sandbox), you see a Security Warning dialog that says:

> "If you allow this app, it can access your data and act on your behalf. If someone contacted you via phone or email and instructed you to use this app, do not proceed."

**Explanation:** This is expected behavior. Salesforce displays this warning for all third-party connected apps as a security measure, particularly after security updates in Spring '26. This is not an error.

**Solution:**

1. Verify you initiated this connection from within SRE.ai
2. Review the permissions SRE.ai is requesting:
   * Access the Identity URL service
   * Manage user data via APIs
   * Perform requests at any time
3. Click **Allow** to authorize the connection
4. You'll be redirected back to SRE.ai with your instance connected

**Note:** This warning appears when connecting Salesforce instances for deployments, not when using Salesforce as a login method. Both production and sandbox connections will show this warning.

#### Connecting Sandbox shows the production login screen

**Symptom:** When clicking "Connect Sandbox," you're directed to `login.salesforce.com` (the production login URL) instead of `test.salesforce.com` (the sandbox login URL).

**Solution:**

1. On the Salesforce login screen, click **"Use Custom Domain"**
2. Enter your sandbox domain (e.g., `your-sandbox-name.sandbox.my.salesforce.com`)
3. Log in with your sandbox credentials
4. Complete the authorization

The URL should resolve to your sandbox instance once you specify the custom domain.

## Salesforce login issues

#### Salesforce login works after revoking old OAuth installations

**Symptom:** You've tried multiple times to log in with Salesforce but keep getting errors or redirect loops, even after verifying permissions.

**Possible Cause:** Old or stale OAuth installations in your Salesforce user profile may have incorrect permissions cached.

**Solution:**

1. In SRE.ai, click your user profile in the top right
2. Scroll down to find existing OAuth installations
3. Revoke all installations related to SRE.ai (or similar apps like "Asari.ai" if present)
4. Try logging in again, you should be prompted to authorize the app fresh
5. Complete the authorization with current permissions

This clears any cached permission issues and establishes a clean connection.

#### Unverified email blocking login

**Symptom:** Salesforce login fails even though you can see the authorization screen and click "Allow."

**Possible Cause:** If your organization uses SSO, your email may not be verified in Salesforce, which can block third-party app authorization.

**Solution:**

1. Check if your email is verified in Salesforce:
   * Go to Salesforce Setup → Users → find your user record
   * Look for the email verification status
2. If using SSO, your organization may not require email verification. Check with your Salesforce administrator
3. If email verification is required, complete the verification process in Salesforce
4. Retry logging into SRE.ai

#### OAuth error during login

**Symptom:** When attempting to log in with Salesforce, you see an error screen displaying:

> OAuth Error
>
> We can't authorize you because of an OAuth error. For more information, contact your Salesforce administrator.
>
> OAUTH\_APPROVAL\_ERROR\_GENERIC: An unexpected error has occurred during authentication. Please try again.

**Possible Causes:**

* Your Salesforce user profile doesn't have the required API permissions
* Your organization hasn't authorized SRE.ai as a connected app
* Your organization has security policies that restrict third-party application access

**Solutions:**

1. **Verify your Salesforce user profile has API access enabled:**
   * In Salesforce, go to Setup → Users → find your user profile
   * Check that **"API Enabled"** and **"Approve Uninstalled Connected Apps"** are turned on in your profile permissions
   * If you don't have permission to check these, ask your Salesforce administrator
2. **Check if SRE.ai is authorized as a connected app:**
   * In Salesforce Setup, go to Apps → Connected Apps → Manage Connected Apps
   * Look for SRE.ai in the list
   * If it's not there, your organization may need to authorize the app before users can log in with Salesforce credentials
3. **Ask your Salesforce administrator to enable external app authorization:**
   * Some organizations have security policies that require admin pre-approval for connected apps
   * Your admin may need to enable a permission that allows users to authorize external applications
4. **Use an alternative login method:** If Salesforce login continues to fail, you can log in using Microsoft Teams or Google instead. Your account will be linked automatically, and you can connect your Salesforce instances separately after logging in.
5. **Contact SRE.ai support:** If the issue persists after verifying permissions, reach out to our team. Provide the approximate time of the error so we can check our logs.

{% hint style="danger" %}
**Logging into SRE.ai with your Salesforce credentials is separate from connecting your Salesforce instances for deployments.**

Even if you log in with Google or Microsoft Teams, you can still connect your Salesforce orgs through the Instances setup.
{% endhint %}

#### Password expired error

**Symptom:** When attempting to log in with Salesforce, you receive a message that your password has expired.

**Solution:**

1. Reset your password directly in Salesforce
2. Once your Salesforce password is updated, return to SRE.ai and try logging in again

{% hint style="info" %}
SRE.ai uses your live Salesforce credentials for authentication.

If your Salesforce password expires or changes, you'll need to use the updated credentials to log in to SRE.ai.
{% endhint %}

#### Login redirect loop

**Symptom:** After entering your Salesforce credentials and authorizing the connection, you're redirected back to the SRE.ai home page without being logged in. Attempting to log in again produces the same result.

**Possible Causes:**

* A session establishment issue between SRE.ai and Salesforce
* Browser cookie or cache conflicts

**Solutions:**

1. **Clear your browser cache and cookies** for both `sre.ai` and `salesforce.com` Then, try logging in again.
2. **Try a different browser or an incognito/private window:** This rules out conflicts with browser extensions or cached session issues.
3. **Use an alternative login method:** Sign in through Microsoft Teams or Google. Once logged in, you can establish your Salesforce connection separately through the Instances setup. Your accounts will link automatically.
4. **Contact SRE.ai support** if the issue persists across browsers and login methods. Include details on when the issue started and any error messages you've seen.


# Integrations troubleshooting

## Jira integration issues

#### OAuth scopes error when connecting Jira

**Symptom:** After creating an OAuth app in the Atlassian Developer Console and entering the credentials in SRE.ai, you receive an error related to scopes or permissions.

**Cause:** The OAuth app in Atlassian requires specific API scopes to be configured before SRE.ai can connect.

**Solution:**

1. Go to the [Atlassian Developer Console](https://developer.atlassian.com/console/myapps/)
2. Select your SRE.ai OAuth app
3. Go to **Permissions** in the left sidebar
4. Add the **Jira API** permission
5. Configure the following scopes:
   * `read:jira-work` — View Jira issues and projects
   * `write:jira-work` — Create and manage issues
   * `read:jira-user` — Read user information
   * `offline_access` — Maintain access via refresh tokens
6. Go to **Authorization** in the left sidebar
7. Click **Add** next to "OAuth 2.0 (3LO)"
8. Enter the callback URL provided by SRE.ai
9. Save and return to SRE.ai to retry the connection

#### Jira integration is limited to certain projects

**Symptom:** After connecting Jira, you can only see or interact with some projects, not all projects in your Atlassian workspace.

**Cause:** The Jira integration inherits the permissions of the user who created the OAuth app. If that user doesn't have access to certain projects, SRE.ai won't be able to access them either.

**Solution:**

1. Have a user with broader project access create the OAuth app, or
2. Ensure the user who created the OAuth app is granted access to the necessary Jira projects

{% hint style="info" %}
You can create one OAuth app for your entire Atlassian organization. There's no need for a per-project approach.
{% endhint %}

## GitLab connection issues

#### Missing or incorrect OAuth app scopes

**Symptom:** After entering your GitLab OAuth credentials in SRE.ai, the connection fails or certain operations (repository access, push event handling) don't work.

**Cause:** The GitLab OAuth app requires specific scopes to be granted during creation.

**Solution:**

When creating your OAuth app in GitLab (under **User Settings → Applications** or the Admin Area for group-level apps), ensure all four scopes are checked:

* `api` — Full API access, required for repository operations and MR management
* `read_user` — Read user profile information
* `read_repository` — Read repository contents
* `write_repository` — Push commits and manage branches

If you created the app without all scopes, you'll need to edit the app in GitLab and re-authorize in SRE.ai.

#### Self-hosted GitLab URL not accepted

**Symptom:** When connecting a self-hosted GitLab instance, SRE.ai fails to redirect to your GitLab login page, or returns an error after authorization.

**Solution:**

1. Ensure the GitLab URL field in SRE.ai contains the full base URL of your instance (e.g., `https://gitlab.yourcompany.com`)
2. Do not include a trailing slash or `/api/v4` path — SRE.ai appends the API path automatically
3. Confirm your instance is reachable from the internet (or that SRE.ai has network access to it)
4. Verify the OAuth app's **Redirect URI** in GitLab matches the callback URL shown in SRE.ai

#### Webhook events not triggering pipeline actions

**Symptom:** Pushes or merge requests in GitLab don't appear to trigger SRE.ai automations or pipeline updates.

**Cause:** GitLab webhooks use a secret token (`X-Gitlab-Token`) for verification. If the token in GitLab doesn't match what SRE.ai has stored, all webhook events are rejected with `401 Unauthorized`.

**Solution:**

1. In SRE.ai, go to your pipeline or integration settings and copy the webhook secret
2. In GitLab, go to your repository or group → **Settings → Webhooks**
3. Find the SRE.ai webhook entry and verify the **Secret token** matches exactly
4. If unsure, delete the webhook and re-add it with the correct secret from SRE.ai
5. Use GitLab's **Test** button on the webhook to confirm events are being received

#### GitLab integration only sees some repositories

**Symptom:** After connecting GitLab, SRE.ai can only access a subset of your repositories.

**Cause:** The GitLab integration uses the OAuth token of the user who connected it. That user's visibility determines which repositories SRE.ai can access.

**Solution:**

Have a user with the appropriate access level (at minimum **Developer** role on the relevant projects) connect the GitLab integration, or ensure the connecting user is added to all required projects.

## GitHub connection issues

#### Connection works on initial setup, but fails on updates

**Symptom:** You initially connected GitHub, but when you try to update repository access (adding or removing repositories), the changes don't seem to take effect, or you're not redirected back to SRE.ai.

**Solution:**

1. **Return to SRE.ai manually:** After updating your GitHub app installation settings, navigate back to SRE.ai directly. Your updated repository access should be reflected.
2. **Verify in GitHub:** Go to your GitHub organization settings → Installed GitHub Apps → SRE.ai GitHub App to confirm your repository selections were saved.
3. **Reconnect if needed:** If the connection appears broken, you can remove the SRE.ai GitHub app from your organization and reinstall it with the correct repository access.

#### Accidentally connected the personal account instead of the organization

**Symptom:** You connected GitHub, but don't see your organization's repositories, or SRE.ai is connected to your personal repositories instead of your team's.

**Solution:**

1. Go to GitHub → Settings → Applications → Installed GitHub Apps
2. Find the SRE GitHub App and click **Configure**
3. If it's installed on your personal account, click **Uninstall**
4. Return to SRE.ai and click **Connect GitHub Account** again
5. This time, select your **organization** from the list (not your personal account)
6. Choose the repositories you want to connect to and complete the installation


# Contact support

To get in touch with SRE.ai's support team, contact <support@sre.ai>.

Please include:

* A description of what you were trying to do
* The exact error message (a screenshot helps)
* The approximate time the error occurred
* Which login method(s) you tried

This information helps us diagnose the issue quickly.


# Release management strategies

Learn about the principles that inform SRE.ai's Pipelines feature.

## Overview

An effective release management process requires a stable **environment strategy** and a clear **branching strategy**.

Read below to learn about the optimal environment and branching strategies that inform SRE.ai's Pipelines feature.

[Read SRE.ai's Pipelines documentation](broken://pages/skx8XvXxnLwlmMVGvdjg) for more information.

## Environment strategy

An environment strategy defines how software is managed and deployed across environments such as development, testing, and staging. It typically includes automation and configuration controls to keep environments consistent.

In SRE.ai, **instances** connect to Salesforce environments (Production, Sandbox, or Scratch Orgs) and abstract the underlying environment, which may change over time.

Each instance is assigned to a branch that reflects the current state of that environment. You can also connect an instance to a **parent instance** representing the next environment in the release process. For example, a development instance connected to a quality assurance instance.

A parent instance can have multiple child instances, forming a hierarchy. Features flow forward to the parent through the **promote** process and backward to child instances through **back promotion**.

A typical Environment Strategy may look like this:

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FaE4Q7PdIPNRXQ333XDNt%2FScreenshot%202025-08-17%20at%204.52.58%E2%80%AFPM.png?alt=media&amp;token=471339fb-1209-4b86-b16e-ee3262b2a521" alt=""><figcaption></figcaption></figure>

## Branching strategy

A Branching Strategy organizes and stores different versions of code in a source control repository.

A branch represents a separate line of development. Branches enable multiple developers to work on the same codebase simultaneously without affecting each other's work.

SRE.ai uses a hybrid git branching strategy that combines the best of Feature Branching and [GitFlow](https://www.gitkraken.com/learn/git/git-flow).

Developers typically create a separate branch for each new feature. By default, each branch originates from the repository's designated main branch, ensuring the feature builds on stable code.

A repository's main branch doesn't have to be named "main." If you have a long-term project with its own repository, feature branches created from a connected instance will base off that repository's main branch instead. This avoids frequent merging and better aligns with project milestones.

<figure><img src="https://896674903-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FvfI0D9tucHKxynzSIFSd%2Fuploads%2FDu1pwdwiyhfrNap0OWTP%2Fupdated%20graph.png?alt=media&amp;token=433143f7-4540-4042-8136-c349dc815213" alt=""><figcaption></figcaption></figure>


# Security and compliance documents

{% file src="/files/TOAMPHlzKDd98Flf3qQ8" %}

{% file src="/files/iGmYE9cpVGXiF8jhIToZ" %}

{% file src="/files/t5TdvicQpxb3nGiuQXCV" %}

{% file src="/files/C0XvYTPaLoHAk0b9AvEV" %}

{% file src="/files/U8wAP0fe9L21mwlPZq73" %}

{% file src="/files/NkBemLlebshoKVvdInqN" %}

{% file src="/files/cDvnblFH8GlAgpiKM2tQ" %}

{% file src="/files/jVeNkPMlghbf6JjoBsle" %}

{% file src="/files/coiBfxbH4XKO4VfvzUeL" %}

{% file src="/files/OOjtmDNbnNZNk4ooYOG1" %}

{% file src="/files/yyxNCAoHo3QUyta6LjHO" %}

{% file src="/files/p303cw4wa273lI3CNe0q" %}


# Technical Brief: Why We Use GitHub Apps Over OAuth

We use the **GitHub App** framework (the industry-standard recommended by GitHub and Gearset) because it offers a stronger security architecture than traditional OAuth. Unlike OAuth, which grants broad, persistent "act-as-user" permissions, GitHub Apps use **fine-grained permissions** and **short-lived tokens** (expiring every hour) to ensure the Principle of Least Privilege. Furthermore, GitHub Apps allow for **repository-level scoping**, ensuring the tool can only access specific authorized repositories rather than a user’s entire GitHub account.

#### **Platform Documentation & Recommendations**

* **GitHub Official:** [GitHub Apps are the recommended way to integrate](https://docs.github.com/en/apps/creating-github-apps/about-creating-github-apps/deciding-when-to-build-a-github-app). Examples of other products:
* **Gearset:** [Recommends its GitHub App](https://docs.gearset.com/en/articles/9965863-integrating-with-github-or-github-enterprise-through-a-github-app) to eliminate broad OAuth scopes. They *have* an alternative OAuth-based connection method, but do not recommend it.
* **Copado:** [Utilizes an OAuth2-based approach](https://docs.copado.com/articles/copado-ci-cd-publication/git-repository-overview) non-specific to GitHub to secure credentials within backend secrets stored in Copado systems.

| **Security Feature**       | **GitHub App (Recommended)**                                                                 | **OAuth App (Alternative)**                                                    |
| -------------------------- | -------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------ |
| **Permission Granularity** | **Fine-grained:** Separate "Read" vs "Write" for code, PRs, and metadata.                    | **Broad Scopes:** `repo` scope grants full control over all code and settings. |
| **Credential Lifetime**    | **1 Hour:** Tokens are temporary and auto-rotated.                                           | **Indefinite:** Tokens live forever until manually deleted.                    |
| **Access Control**         | **Repository-level:** You choose exactly which repos are visible.                            | **Account-level:** Accesses everything the user can see.                       |
| **Traceability**           | **Bot-Specific:** Actions are clearly marked as the integration (co-authored with the user). | **User-Impersonation:** Actions appear as if the user performed them.          |
| **Service Stability**      | **Independent:** Works even if the setup user leaves the company.                            | **User-Dependent:** Breaks if the authorizing user’s account is deactivated.   |


# Automations cookbook